Customer portal
Articles Tagged with
cyber threat intelligence

"Lightning
Investigation, Uncategorized

The Victims That Show Up Twice

What’s really behind ransomware’s repeat listings

Spend enough time working through ransomware leak sites, and you start to notice something odd. A company gets named by one group, its stolen files posted, a countdown clock ticking away next to its logo. Then, weeks or sometimes months later, the same company turns up again, this time under a completely different group’s banner.

At first glance, it looks like the worst kind of bad luck: a firm hit twice by two unrelated criminal operations, back to back. We wanted to know how often that’s actually true, and it turns out the honest answer is: not very often, and rarely for the reason you’d assume.

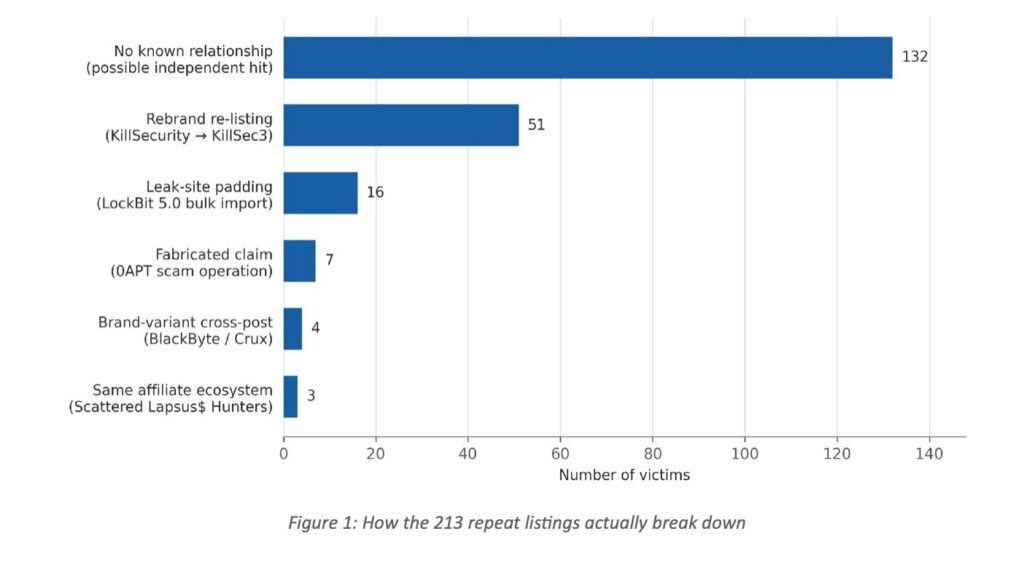
Working through just under 14,000 victim listings scraped from leak sites between July 2024 and June 2026, matched up by company domain and name, we found 213 organisations that had been named by more than one group, out of 12,782 distinct victims in the dataset, roughly one in sixty. Not a huge share, but far from nothing, and once we started checking the reasons behind it, the picture got considerably stranger than “two gangs happened to pick the same target”.
Not everything that looks like a double hit is one

The first thing we had to rule out was our own data getting confused. Some apparent overlap is just noise: a leak site occasionally records a file-hosting link or a LinkedIn profile in the space where a company’s domain should go, and several unrelated victims end up sharing that same non-domain value purely by coincidence. Strip that out, and what’s left starts to look like genuine repeat appearances. Even then, a good chunk of them aren’t quite what they seem.

Take KillSecurity. It ran a leak site from mid-2024 until early 2025, then went quiet. In August 2025, a new site appeared calling itself KillSec3, and threat intelligence trackers list KillSec3 as simply the next iteration of the same operation, not a rival. Sure enough, on 10 October 2025, KillSec3 posted 169 victims to its site. Fifty-one of those matched victims were already listed under the old KillSecurity name months earlier. That isn’t two gangs hitting the same target. It’s one gang moving house and bringing its old address book along.

LockBit’s comeback tells a similar story, for slightly different reasons. LockBit 5.0 launched in December 2025, nearly two years after Operation Cronos, the February 2024 law enforcement takedown that had hobbled the group, and it needed to look busy fast. Every one of its biggest posting days in our data arrives as a burst rather than a trickle: 34 victims added on one occasion, 62 on another. Reporting on the relaunch noted that the new site’s victim list included recycled entries from earlier LockBit versions, and even from unrelated groups altogether. Sixteen of the overlapping victims in our dataset were caught up in one of these LockBit 5.0 bulk-import bursts, which has the hallmarks of padding a leak site to look credible rather than genuinely fresh attacks.

Then there’s BlackByte and a newer offshoot calling itself Crux, first spotted by researchers in July 2025. Crux’s own ransom notes state outright that it’s “part of BlackByte”. In our data, four victims turn up under both names, posted on the same day. Same operation, two labels, one victim.

Add those three explanations together, and you account for 71 of the 213 apparent double-victims, roughly a third of the total, without a single fresh attack among them.

The gang that turned out to be a hoax

One entry deserves its own section because it’s the clearest illustration in the whole dataset of why a leak site listing should never be taken at face value on its own.

In late January 2026, an outfit calling itself 0APT appeared from nowhere and, within about a week, claimed more than 200 victims. That kind of volume normally takes an established group years to build up, and it set off alarm bells immediately. Researchers at GuidePoint, Intel 471 and S-RM independently reached the same conclusion within days of each other: the list was largely fabricated, mixing invented company names with real, recognisable ones, seemingly so the fake entries would look more credible sitting next to genuine household brands. One invented victim, “Metropolis City Municipal”, turned out to be lifted straight from the fictional city in the DC Comics universe. When researchers tried to download the “stolen data” 0APT claimed to be holding, the files were masked to look hundreds of gigabytes in size and never actually finished downloading. In April 2026, a rival outfit called KryBit hacked 0APT itself and published its internal logs, confirming the entire 190-plus victim list had been invented from the start.

Seven of the 213 double-listed companies in our dataset, including Foxconn, Stryker, Medtronic and Ingersoll Rand, owe their second appearance entirely to 0APT. None of that is a second ransomware attack. It’s a scam operation borrowing the credibility of a well-known name, sitting next to a genuine listing from an entirely different, unrelated group. We’ve pulled these seven out of the “unexplained” total and given them their own category, because lumping a fabricated claim in with a genuine repeat attack would badly overstate how often real double-victimisation actually happens.

The pattern actually worth paying attention to

There’s a fourth explanation, and this is the one that matters most if you’re trying to understand how modern extortion actually works.

On 3 October 2025, a group calling itself Scattered Lapsus$ Hunters posted an enormous batch of household names in one sitting: Toyota, FedEx, Disney/Hulu, Home Depot, Adidas, Chanel, Qantas, dozens more, all within a few hours. This was the fallout from the Salesforce-linked data theft campaign that made headlines at the time. Three to six months later, a handful of those same companies, CarMax, Cisco and Engie among them, reappeared, this time under the names ShinyHunters or Coinbase Cartel.

Those names aren’t unconnected. Threat intelligence assessments describe Coinbase Cartel as drawing on the same affiliate pool as Scattered Lapsus$ Hunters, with both ShinyHunters and Scattered Spider named among its contributors, and flag a specific pattern: collect a ransom, then come back under a different name demanding more, often over data the victim thought had already been dealt with. When Cisco appears under ShinyHunters roughly six months after showing up in the Scattered Lapsus$ Hunters mega-post, that isn’t a second breach. It’s the same stolen data being squeezed for a second payment, wearing a different mask.

It only accounts for three confirmed cases in our data, and almost certainly more sit undetected, given how loosely some of these victims were named in the original mass listing. But it’s the pattern that best explains why “same victim, different gang” doesn’t necessarily mean what it looks like on the surface.

What’s left: 132 with no obvious explanation

Strip out the rebrands, the copycats, the fabricated claims and the shared-affiliate cases, and you’re left with 132 companies where we found no rebrand, copycat or shared-affiliate link between the two groups that named them. That makes 132 an upper bound, not a confirmed count of genuine double hits: it’s what remains once every explanation we could actively verify has been ruled out, not a figure we’ve independently proven case by case. Some of the 132, as the case studies below show, do stand up as genuine coincidental double hits. For others, the explanation may simply be one that isn’t visible in public reporting.
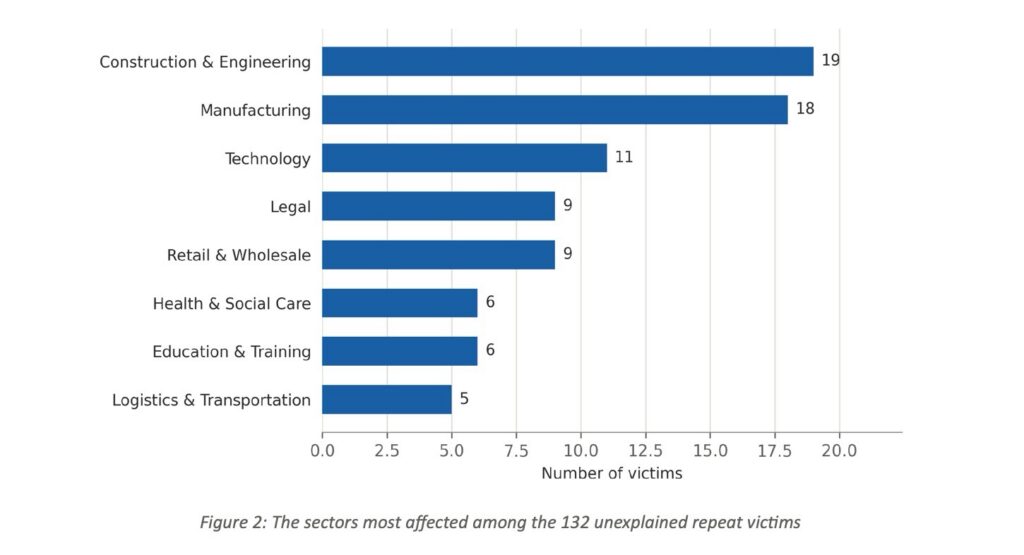
A few things stand out about this group. Roughly two-thirds are American companies. Construction and manufacturing firms turn up more than any other sector, which lines up with what most ransomware reporting already tells us: these industries tend to run older, less segmented infrastructure and can rarely afford to take systems offline to patch them properly.
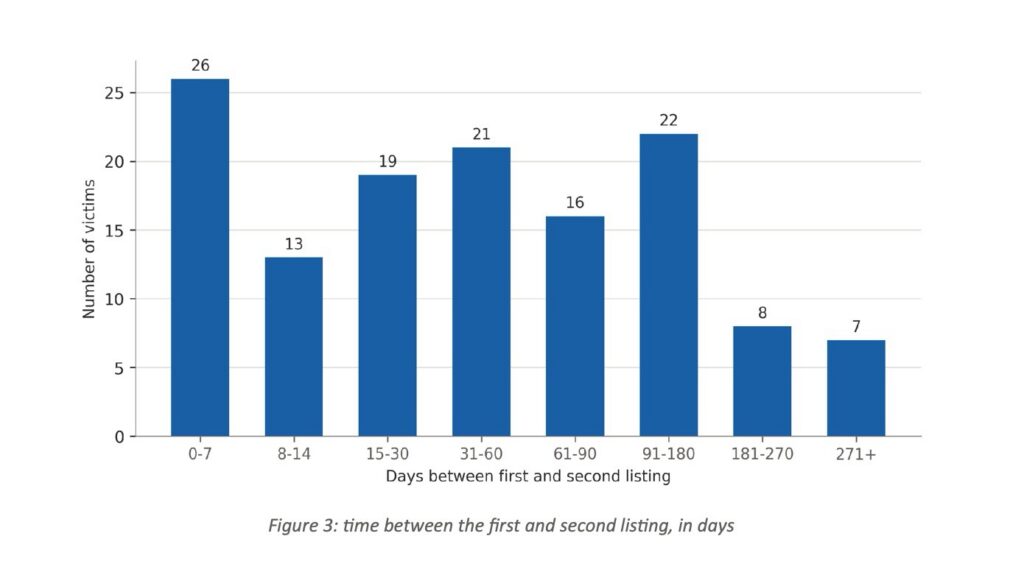
The gap between the first and second listing varies wildly, from the same day to fourteen months, though a gap of around six weeks is typical. That’s usually long enough to suggest this isn’t the same stolen access simply being resold within days of the first sale.

Five companies were named by three separate groups rather than two. Nationwide Legal LLC turns up under KillSecurity, KillSec3 and Medusa. Defence and technology firm L3Harris was claimed by Kyber, the Gentlemen and WorldLeaks across a seven-month stretch. Spanish pharmaceutical firm DARA Pharma appears under BlackByte, its Crux offshoot, and WorldLeaks, all within eleven days of each other, hinting that the same underlying breach may simply have been spotted and claimed by more than one outfit at once.

Five names we checked, five different answers

Numbers only tell you so much, so we picked out some of the more recognisable names from the 132 and went looking for public reporting to see whether the “double hit” actually holds up. The results were, frankly, all over the place, which turns out to be rather the point.

Volkswagen Group: the strongest case for a genuine double hit

Our data shows Volkswagen listed twice, first by 8Base, then by Stormous. The 8Base claim surfaced in autumn 2024: the group said it had stolen invoices, employee records and contracts, with Volkswagen confirming to ITPro and other outlets that it was dealing with an “incident” while insisting its core IT systems were unaffected. 8Base was then disrupted by a Europol-led takedown in February 2025, with arrests made in Thailand. Some months later, an entirely separate group called Stormous listed Volkswagen again, this time claiming something different altogether: authentication tokens, session cookies and vehicle identification numbers, as reported by Cyber Daily and teiss. Two unrelated groups, two different sets of stolen data, the best part of a year apart. This is about as clean a genuine double hit as the dataset produced.

Harvard University: the best-evidenced case in the dataset

Clop listed Harvard in October 2025 after breaching the university through a zero-day flaw in Oracle’s E-Business Suite software, part of a campaign that hit dozens of Oracle customers worldwide and which Harvard confirmed to Dark Reading and the Harvard Crimson affected “a small administrative unit”. Completely separately, ShinyHunters, working under the wider Scattered Lapsus$ Hunters banner, got into Harvard’s Alumni Affairs and Development systems through social engineering aimed at staff logins rather than any Oracle software. That breach was first disclosed to affected alumni in November 2025, and the stolen data was published in full once negotiations broke down in February 2026, as TechCrunch reported at the time. Different attackers, different entry points, different parts of the university, roughly a month apart. If you wanted one case to point to as proof that “same victim, different gang” can be exactly what it looks like, this is it.

Comcast: the first half doesn’t actually hold up

Medusa listed Comcast in September 2025, claiming 834 gigabytes of stolen data, including actuarial reports and insurance modelling scripts. The trouble, as Cybernews pointed out at the time, is that Comcast doesn’t do insurance underwriting, and the file types described match an entirely different kind of company. Analyst Dominic Alvieri suggested the data likely belonged to an unrelated insurance firm that Medusa had simply mislabelled. Comcast never confirmed the breach either way. We couldn’t find independent reporting confirming the second listing, by Space Bears in December 2025, at all. A useful reminder that a leak site claim isn’t evidence in itself, and sometimes the company named isn’t even the right one.
BMW Group: half confirmed

Everest’s September 2025 claim against BMW, alleging the theft of 600,000 lines of audit data, was extensively covered by Cybernews and others, arriving days after Jaguar Land Rover’s much larger, production-halting breach had already put the whole sector on edge. BMW never confirmed it. The second listing in our data, by a group called CipherForce, roughly six months later, didn’t turn up in any public reporting we could find. Call this one open.

L3Harris: less a double hit, more a habit

The American defence contractor appears three times in our own data (Kyber, the Gentlemen and WorldLeaks), and widening the search turns up still more: the Abyss group claimed access to its satellite systems back in 2023, and a separate outfit called Anubis listed the company again in June 2025. Of these, WorldLeaks’ August 2025 claim is the best evidenced, backed by screenshots that Cyber Daily verified as genuine internal chat messages between L3Harris staff and a recently acquired subsidiary. A company that builds systems for the F-35 and the proposed Golden Dome missile shield is, unsurprisingly, the kind of name opportunistic groups like to claim, whether or not they can back it up. Sometimes a “double hit” isn’t really about two attacks at all. It’s about how attractive a target has become.

Stopping lightning from striking twice

Look again at the cases from the last section, and something worth noticing emerges: the kind of thing that’s easy to miss when you’re staring at a list of group names rather than a timeline. Volkswagen’s two hits were the best part of a year apart. Harvard’s were roughly a month apart. In neither case did the second attacker walk in through the same door as the first: Clop exploited a zero-day in Oracle’s software, while ShinyHunters got in through a phished login belonging to Alumni Affairs staff. Volkswagen’s two attackers appear to have found entirely separate routes in as well.

That’s worth sitting with, because it cuts against the natural assumption that a second attack must mean the first breach was never properly cleaned up. Sometimes it does mean exactly that. It’s also consistent with a wider pattern reported across ransomware and extortion cases generally: employee credentials sitting in infostealer logs, in some cases for years, long before anyone thought to use them. We haven’t confirmed that mechanism inside these 132 cases specifically, but it doesn’t need to have happened that way for the underlying point to hold. The first breach and the second one don’t need to share a cause. They only need to share the same underlying gap: nobody was keeping watch on what was already circulating about that organisation on the dark web.

That’s the uncomfortable part of assuming lightning doesn’t strike twice. For an organisation that has just been through a ransomware listing, the instinct is to patch the specific hole that let that one group in, then move on. The genuine double hits in this dataset suggest that it’s necessary, but rarely sufficient on its own. A company can fix the exact vulnerability an attacker used and still be sitting on an entirely separate exposure, a reused password, an old infostealer infection nobody ever traced back to its source, a set of employee credentials still doing the rounds on a criminal marketplace, that a second, unconnected group eventually stumbles onto.

It’s worth asking, in the aftermath of any breach, not only “how do we stop this happening again?” but “how did they actually get in, and is that route still open?” Leak site claims themselves rarely answer either question, and as the Comcast case shows, they don’t always even name the right company. That’s usually only answerable by looking at what’s actively being said and traded about an organisation on dark web forums and marketplaces, rather than waiting for the next listing to explain it after the fact. It’s precisely that gap, between an initial breach and whatever comes next, that continuous dark web monitoring exists to close: catching exposed credentials and early chatter before they turn into a second listing, and helping establish how the first one happened rather than simply writing it off as bad luck. It’s the kind of visibility we build into our own monitoring work at SOS Intelligence, among others in this space.

For the 132 companies in this dataset with no identified explanation for their second listing, the gap between listings, weeks in some cases, the best part of a year in others, was a time during which nobody appears to have been watching. That’s the part worth changing.

Why this actually matters

If your company’s name turns up on a leak site, the obvious question is whether that’s the end of it. This analysis, and the cases we researched, suggest the honest answer is: it depends entirely on who’s doing the naming and how much of their claim you can actually verify, and neither is obvious from the outside looking in.

Sometimes a second listing is nothing more than admin, a group rebranding and carrying its old case files along for the ride. Sometimes it’s a scam artist borrowing a household name to look credible. Sometimes, particularly where a large supply-chain breach is involved, it’s a genuine second squeeze: the same data, a different name, another deadline. And for up to 132 of the 213, once every explanation we could actively verify has been stripped out, it may look like exactly what it appears to be on the surface: bad luck striking twice, from two entirely separate directions. The Harvard and Volkswagen cases show that this does genuinely happen. But 132 is a ceiling, not a confirmed count, and the five case studies above show how easily an unverified listing can turn out to be something else entirely.

The lesson for anyone trying to make sense of this, whether you’re defending a network, reporting on one, or simply trying to work out what a leak site listing actually means, is the same one that applies to most things in this line of work. Check who’s really behind the name, check whether they can prove what they’re claiming, and only then start assuming the worst.

Analysis based on 13,916 leak-site listings covering 1 July 2024 to 30 June 2026, matched across groups by domain, exact name and fuzzy name matching. Known rebrand, affiliate and scam relationships were checked against public threat intelligence reporting and news coverage; the five named case studies were individually verified against public reporting as of July 2026.

Header image by Micah Tindell on Unsplash

BMW by Zan Lazarevic on Unsplash

"Cryptocurrency
Investigation, The Dark Web

Cryptocurrency Fraud Tools: A Dark Web Marketplace Analysis

Introduction

Cryptocurrency has become the preferred currency of the underground. It is fast, pseudonymous, and global. But it is also the target. Between theft, wallet draining, and outright fraud, the crypto space is losing billions every year.

In 2024 alone, wallet drainers stole over $500 million, according to Chainalysis’ 2025 Crypto Crime Report. That is not ransomware victims paying extortion demands. That is not clever social engineering or advanced persistent threats. That is simple, scalable fraud at an industrial scale. And the tools to do it are not hidden behind nation-state firewalls or elite darknet forums. They are on sale on what amounts to the Tor equivalent of Amazon.

SOS Intelligence has been tracking these marketplaces for months. We have documented the tools, the prices, the threat actors, and the money laundering pipelines. This analysis is what we found.

What We Found on DARKSEARCH

DARKSEARCH is one of the larger dark web marketplaces. It functions as a general vendor platform, not unlike eBay, but for illegal goods and services. On it, you can buy access to botnets, stolen data, hacking tutorials, or custom malware. You can also buy cryptocurrency theft tools.

The range of products is striking. These are not theoretical exploits or academic proofs of concept. These are working tools used in active campaigns against real targets. Here is what we documented.

Wallet and Account Theft

The simplest products on sale are stolen wallets. Vendors list wallets with substantial balances, already compromised and ready to be drained. A single listing might contain 599 BTC wallets, with individual wallet values ranging from $42,000 to $59,900 USD at 2024 exchange rates. These are not guesses or projections. These are actual wallets with known, verified balances. On markets like Tor Amazon (tamazoncmlw2ohkbsmqxnotudejdd4befrasxuigzzjumqu3zba535yd[.]onion), vendors openly advertise wallets with balances verified as of the day of listing.

Atomic Wallet credentials are also available. Atomic is a popular mobile and desktop wallet used by millions of crypto holders. The Atomic Wallet hack of June 2023 resulted in over $35 million in losses attributed to the Lazarus Group, and compromised credentials continue to circulate on dark web markets. Vendors offer compromised Atomic Wallet accounts containing 1 BTC or more, priced around $4,000 per account. The compromise is complete, meaning the original owner has already been locked out.

Beyond full wallets, you can buy seed phrases and private keys. These are the master credentials that unlock a wallet. A Bitcoin seed phrase recovery tool fetches $1,500 to $6,500, depending on the number of target wallets and recovery likelihood.

Password and Passphrase Cracking Tools

Password protection on wallets assumes the password is strong. It usually is not. So vendors offer specialised tools to crack wallet passphrases at scale. A wallet.dat passphrase cracker, which targets the encrypted wallet file format used by Bitcoin Core and older wallet software, sells for around $400. It performs brute force attacks on the passphrase, trying millions of combinations until it finds the correct one.

These tools are not slow. Modern GPU acceleration can test tens of billions of passwords per second. A weak passphrase, or one based on common patterns, will fall in minutes or hours. A strong one might take days. But the attacker does not need to be fast. They can run the crack in the background indefinitely.

Fake Token Senders and Spoofing Tools

One of the most audacious fraud vectors is the fake USDT sender. USDT is Tether, the largest stablecoin in circulation. Someone using a fake USDT sender can create a fraudulent transaction that appears on the blockchain, complete with the correct token contract address, that shows as sent from one wallet to another. To an untrained eye, it looks legitimate. To a crypto exchange or automated system relying on blockchain scans, it might be legitimate.

These tools sell for $300 to $500. They are typically paired with phishing campaigns. A victim receives a message claiming they have won an airdrop, or that a trade executed successfully, and they see the fake USDT in their wallet. When they try to withdraw or sell it, they are prompted to approve a smart contract transaction. At that point, the drainer takes control. Such tools are actively marketed on platforms like Dark Web World (worldyyyi2ktoisdqjjq4zlt3jftejabo443lb67pfofr2i5gqlkaoqd[.]onion), which hosts a Financial Tools category alongside hacking services.

Reverse Transaction Tools

Bitcoin transactions are supposed to be irreversible. That is part of the design. So the idea of a reverse transaction tool sounds like science fiction. But the vendors of these tools are selling something close to it. A BTC Reverse Transaction Tool, priced between $400 and $600, works by finding transactions on the blockchain that have not yet been fully broadcast to all network nodes. The tool allows the attacker to broadcast a conflicting transaction first, causing the original to be rejected by the network. The BTC then flows to the attacker instead.

This only works on a small fraction of transactions. But it is effective enough that people are paying for it. And the demand suggests it is working in practice.

Mnemonic Brute Force Tools

A BTC mnemonic brute tool costs around 690 USD or 550 GBP. It generates or guesses Bitcoin seed phrases and checks them against the blockchain to see if they contain funds. Because seed phrases follow the BIP39 standard, which is deterministic, a brute force attack on the space of possible mnemonics is theoretically feasible. The attacker generates thousands or millions of seed phrases, derives the public addresses from each one, and queries the blockchain for balances. Advanced Hacking Tools (zqi3evypxq7ok3gqnimwnlesf6v76ksrpgtgb6j7hh6ye752apzmceyd[.]onion) explicitly lists Cryptocurrency Scam Scripts among its offerings, with 38,530 visits and customer reviews confirming ‘software delivered instantly and fully functional’ and ‘secure transaction and smooth process.’

The computational cost is high. But cloud computing makes it cheap. A determined attacker can lease GPU resources for hours or days at a fraction of a cent per compute hour, making the economics viable for high-probability targets.

Leaked Data and Account Databases

Finally, vendors are selling access to compiled databases of leaked credentials. One listing offers access to 16 billion compromised accounts. The seller claims these are de-duplicated and verified against live services. The price is $121,484. That works out to less than one cent per compromised account. For a cyber criminal running wallet-draining campaigns, this is cheap reconnaissance. They can cross-reference stolen exchange login credentials against wallet addresses to identify holders with known balances. Multivendor platforms like Tor Market (sqw2klzo4mtwvbf3by7irjv7r5mdojxwziuus3lh6rketlkggvsdyaad[.]onion) support both Bitcoin and Monero payments, with dedicated Money Transfer categories facilitating these database sales.

Wallet Drainers as a Service

The real innovation on the dark web is not individual tools. It is the business model. Wallet drainers are offered as a service, DaaS, and it is a lucrative franchise.

How DaaS Works

So the architecture of a wallet drainer is straightforward. The developer publishes a toolkit consisting of a drainer contract (a smart contract deployed on-chain) and a user interface for creating phishing campaigns. A criminal rents the drainer, paying either a flat fee or a percentage of stolen funds. They set up a phishing website that mimics a popular crypto exchange or NFT marketplace. They send phishing links to targets via email, SMS, or social media.

When a victim clicks the link, they see a fake login screen or a fake approval request. If they enter their seed phrase or approve a transaction signature, the drainer gains the ability to control their wallet. The funds are transferred immediately to the attacker’s address. The entire flow from click to theft takes seconds.

The drainer operator keeps a percentage. The drainer developer keeps a percentage. The affiliate who promoted the drainer keeps a percentage. Everyone gets paid. It is a lean, distributed criminal supply chain.

Angel Drainer

Angel Drainer is perhaps the most notorious wallet-drainer family in operation. It is believed to have stolen over $25 million in cryptocurrency. It was active from early 2023 through 2024, and operated as a DaaS offering custom drainer contracts and campaign management tools. ScamSniffer blockchain security research has tracked Angel Drainer operations across multiple victim wallets.

Angel users could log into a dashboard, select their target blockchain, customize their phishing site, and launch their campaign. The drainer provided metrics on click-through rates, approval signatures collected, and stolen funds. It was, in essence, a SaaS offering with a criminal payload. Many law enforcement agencies have attributed wallet drains totalling in the millions of dollars to Angel Drainer operators.

Inferno Drainer

Inferno Drainer is believed to have stolen over $80 million. It operated in parallel with Angel Drainer and was arguably more technically sophisticated. Its phishing interfaces were higher fidelity, its blockchain support was broader, and its operational security was tighter. SlowMist blockchain security research has documented Inferno’s operational patterns across multiple victim reports.

In a striking twist, Inferno Drainer operators were observed transferring stolen funds directly to Angel Drainer wallets in several high-value campaigns. This suggests either a partnership or a buyout. It is unclear if Inferno has exited the market or if operations have simply gone underground or rebranded.

Pink Drainer

Pink Drainer operated more transparently than most. The operator ran an active Telegram channel and took custom contracts and integration requests. Pink is estimated to have commanded 28% market share of the wallet drainer space before exiting in May 2024. By that point, it was believed to have stolen tens of millions of dollars.

The operator announced the exit via a single Telegram message, claiming to be retiring. No law enforcement action was publicly attributed to the exit, suggesting the operator likely had good operational security and may be operating new campaigns under a different name.

Technical Breakdown

Understanding how these tools work requires looking at the mechanics of each attack vector. So let’s walk through them.

Mnemonic Crackers and Brute Force

A Bitcoin seed phrase, or mnemonic, is a sequence of 12, 15, 18, 21, or 24 English words. The words are drawn from the BIP39 word list, which contains exactly 2048 words. This means a 12-word seed phrase represents 2048^12, or roughly 5 x 10^39, possible combinations. That is astronomically large. But it is also finite.

A mnemonic brute force tool does not generate mnemonics randomly. Instead, it uses a wordlist and systematically generates combinations, typically in dictionary order or based on frequency analysis. Each generated mnemonic is used to derive public Bitcoin addresses via the BIP32 standard. The tool then queries a Bitcoin blockchain API or a local blockchain copy to check if those addresses hold funds.

The success rate depends on the blockchain. Bitcoin has around 900 million addresses with at least one transaction. The space of possible mnemonics is enormous, so brute force is impractical for a truly random search. But many users choose weak passphrases or do not add a passphrase at all, and some use common word patterns. Those are the targets.

Cloud GPU providers make the attack economic. For a few dollars an hour, an attacker can spin up instances with NVIDIA H100 GPUs, each capable of deriving and checking thousands of addresses per second. A sustained campaign lasting weeks could check billions of addresses at a marginal cost of fractions of a cent per address checked.

Wallet.dat Password Cracking

Bitcoin Core wallet files are stored in a binary format called wallet.dat. If the wallet is encrypted, the file is encrypted using a passphrase. The passphrase is hashed and used as a key for AES-256 encryption.

A wallet.dat cracker tool first extracts the encrypted private keys from the wallet file. It then performs a dictionary attack, hashing candidate passwords and attempting to decrypt the key material. If decryption succeeds, the tool has recovered the private key and can sign transactions.

The challenge for the attacker is that Bitcoin Core uses key stretching, specifically SHA-512, iterated 100,000 times on the passphrase. This makes brute force slow. Even with GPUs, testing a million passwords against a single wallet takes minutes or hours. But again, modern GPU acceleration and cloud computing make it feasible for high-value targets.

Fake USDT and Token Spoofing

USDT is issued by the Tether company, and on most blockchains, it is implemented as a smart contract. The token contract address is public and well-known. A fake USDT sender exploits this by creating a transaction that mimics a token transfer but is not actually executed on-chain.

The attack works like this: the attacker creates a transaction object that references the correct Tether contract address and shows a fake transfer from one address to another. They do not broadcast it to the blockchain. Instead, they inject it into the victim’s wallet interface or display it in a phishing site as if it had already settled.

When the victim sees the fake token in their wallet, they may attempt to withdraw it or trade it. Most wallets and exchanges check the blockchain for the transaction. But a carefully crafted spoof can appear in the transaction history without being fully confirmed. Victims are then prompted to approve a smart contract transaction to complete the withdrawal or trade. That approval signature is where the drainer takes control.

The trickery is not in the spoofing itself, but in the social engineering that surrounds it. The victim is led to believe they have received free tokens and that they need to take action to claim or access them.

Reverse Bitcoin Transactions

Bitcoin transactions are broadcast to the network and then mined into blocks. Once a transaction is included in a block, it is essentially irreversible. But in the brief window between broadcast and inclusion in a block, a miner or someone with network access can potentially broadcast a conflicting transaction first.

A reverse transaction tool exploits this window. When a victim initiates a high-value transaction, the attacker intercepts the network broadcast or learns of the pending transaction through a mempool monitor. The attacker then constructs a conflicting transaction that sends the same inputs to their own address and broadcasts it to the network with a higher fee.

If the attacker’s transaction is included in a block first, the victim’s original transaction becomes invalid because the inputs have already been spent. The funds flow to the attacker instead. This is sometimes called a mempool race or front-running, and it requires network-level access or partnership with a miner. It is not reliable, but it is effective enough that criminals are paying for it.

Clipboard Hijacking and Browser Injection

A simpler attack vector, but still effective, is clipboard hijacking. Some wallet drainers include code that monitors the victim’s clipboard for wallet addresses. When it detects a Bitcoin or Ethereum address, it replaces it with the attacker’s address.

A user copies a withdrawal address from a trusted source, pastes it into their wallet, and unknowingly sends funds to the attacker instead of their intended destination. The attack is hidden, requires no victim interaction beyond copy-paste, and exploits the assumption that the clipboard is a secure location for temporary data.

Clipboard hijacking is often deployed via browser extensions or by compromising popular wallet software. It is not as profitable as wallet draining, but it is persistent and low effort.

Dark Web Crypto Fraud Markets

Let’s consolidate what we found on dark web marketplaces into a clearer picture.

Wallet Drainer Families and Scale

Wallet drainers are the largest profit engine in crypto fraud. Here is what we know about the major players.

Attack Vectors and Detection Difficulty

Not all crypto fraud is equally easy to defend against. So here is a breakdown of the main attack vectors and how difficult they are to detect.

The Money Laundering Pipeline

Stolen crypto is not useful if the attacker cannot convert it back to cash. So understanding the laundering pipeline is critical to understanding the full economic model of crypto fraud.

Mixing and Tumblers

The simplest laundering step is a mixer, also called a tumbler. A mixer is a service that pools coins from multiple users and then redistributes them in ways that break the chain of custody. If I send 1 BTC to a mixer, I do not get the same 1 BTC back. I get 1 BTC that came from someone else’s deposit.

Mixers are sometimes voluntary services that users employ to protect their privacy. But in the context of stolen funds, they are money laundering tools. Law enforcement has been cracking down on mixing services, but many still operate, especially on the dark web.

Swap Services and Atomic Swaps

Another approach is to convert Bitcoin to a different cryptocurrency that has stronger privacy properties. We found references to swap services running on Tor, such as swp.cx, which claim to execute cryptographic atomic swaps between Bitcoin and Monero without requiring custody of the funds.

The attacker sends BTC to the service, which then sends Monero back to the attacker. Monero is pseudo-anonymous and much harder to trace on the blockchain. From there, the attacker can convert to other coins or cash out to fiat via less-regulated exchanges.

Privacy Coins

Privacy coins like Monero use ring signatures and stealth addresses to obscure the sender, receiver, and transaction amount on the blockchain. A transaction in Monero cannot be traced by following the chain of public addresses. This makes Monero the preferred destination for stolen BTC.

The conversion happens on a swap service or exchange. The attacker loses a small percentage to fees and exchange rates, but gains plausible deniability. Once in Monero, the funds are effectively invisible to on-chain analysis.

Chain Hopping and OTC Markets

The most sophisticated attackers use chain hopping: moving stolen funds across multiple blockchains and currencies before cashing out. Bitcoin to Ethereum to Monero to a stablecoin to a privacy token and back. Each hop adds complexity and expense, but it also significantly increases the cost of forensic analysis.

Finally, the attacker accesses over-the-counter (OTC) brokers, often in countries with weak AML enforcement or corrupt officials. They sell large quantities of crypto for cash, receiving wire transfers to bank accounts in their name or under shell companies. These OTC brokers do not ask difficult questions and are incentivised to facilitate large transactions.

Casino Bonus Exploitation

One lesser-known crypto fraud vector is casino bonus exploitation. Online casinos offer sign-up bonuses to new players: deposit $100, get a $100 bonus. To claim the bonus, you must meet a turnover requirement, usually 30 to 50 times the bonus amount. This is designed to be difficult.

But with access to stolen payment methods and identity documents, a fraudster can create dozens or hundreds of accounts and claim bonuses using different identities. A casino bonus exploitation kit, selling for $150 to $350 on the dark web, automates this process. The kit includes scripts to bypass identity verification, claim bonuses, meet turnover requirements using automated play, and cash out.

The profit margins are high. A $3,000 to $10,000 bonus can be turned into actual cash if the attacker is patient and covers their tracks. The casinos absorb the losses, and usually do not prosecute because of the reputational and legal costs.

Scale of the Problem

To appreciate the scale, consider the raw numbers.

Sixteen billion compromised accounts are for sale on dark web markets. That is more than twice the world population. Many accounts are duplicates across multiple breaches, but the number still represents massive exposure. Any crypto user with an email address used on a commonly breached service is a potential target for credential-based attacks.

Stolen Bitcoin wallets with known balances, in the hundreds or thousands of BTC, are actively listed on the marketplace. These are not speculative. These are wallets that have been compromised and whose balances have been verified.

Wallet-drainer families have collectively stolen $300 million or more in the last two years. Many attacks go unattributed and unreported, especially from users in countries with weak cybercrime reporting infrastructure. The true number is certainly higher.

The tools themselves are cheap. A full-featured drainer costs $100 to $500 per month to rent. A mnemonic cracker is a few hundred dollars. An investment of a few thousand dollars can yield millions in stolen crypto. The economics are favourable for the attacker. They are not.

How SOS Intelligence Monitors Crypto Threats

SOS Intelligence has been monitoring these dark web markets since 2024. Our approach focuses on two core capabilities.

DARKSEARCH Crawling and Indexing

Our DARKSEARCH crawler maintains a running index of major dark web marketplaces, including the venues where crypto fraud tools are sold. We track new tool releases, pricing changes, operator behaviour, and customer feedback. This gives us a real-time view of the threat landscape.

We extract and parse product listings, vendor history, and customer reviews. We track changes in pricing, which often correlate with law enforcement action or shifting market dynamics. When a major drainer family exits or goes dark, we identify the shift early and begin looking for successor operations.

Cryptocurrency Address Monitoring

We also monitor the blockchain itself for known crypto fraud addresses. When a wallet drainer operation is disrupted or a perpetrator is identified, their associated addresses often remain public. We track these addresses for ongoing movement of funds, which can identify new campaigns or money laundering patterns.

By correlating blockchain data with dark web intelligence, we can often connect a phishing campaign to a drainer family, and that family to a money laundering pipeline. This gives our customers early warning before their users are targeted.

Defensive Recommendations

For crypto holders and exchanges, defence is possible. So here is what we recommend.

For Individual Crypto Holders

Use hardware wallets for significant amounts. Hardware wallets store private keys offline and require physical confirmation of transactions. They are resistant to mnemonic cracking, wallet.dat attacks, and phishing.

If you use hot wallets, use strong and unique passphrases. Do not use dictionary words or common patterns. Use a password manager to generate and store passphrases. This makes brute force attacks impractical.

Never approve transactions on suspicious sites or in response to unsolicited messages. Drainers rely on approval signatures. If you do not approve, you do not lose funds.

Monitor your wallet addresses for unauthorised transactions. Set up blockchain monitoring alerts on your addresses. If funds start moving without your action, you can investigate immediately.

Use two-factor authentication on exchange accounts. Many drainers target exchange credentials. MFA, even SMS-based MFA, adds a layer of protection.

For Exchanges and Custodians

Implement withdrawal limits and delays. If a customer’s account is compromised, a withdrawal delay gives the customer time to notice the anomaly and cancel the transaction.

Monitor for suspicious wallet addresses in withdrawals. If a customer is withdrawing to a known drainer address or money laundering service, flag it for review.

Educate users about phishing. Many victims do not realise they have been compromised until weeks after the attack. Clear guidance on how to identify phishing reduces successful attacks.

Implement address whitelisting. Allow customers to whitelist trusted withdrawal addresses and require manual override for new addresses. This blocks many spontaneous account takeovers.

Work with blockchain analysis firms to identify incoming funds from known stolen addresses. Money laundering at scale means some stolen funds flow into honest people’s wallets. Detecting and blocking this upstream reduces the utility of theft.

Conclusion

Cryptocurrency fraud is not a niche problem. It is a $300 million to $500 million per year industry, with efficient, scalable tools and business models. The tools are cheap, the barriers to entry are low, and the margins are enormous.

The most striking finding is not the theft itself, but the industrialisation of fraud. DaaS offerings like Angel Drainer and Inferno Drainer have turned wallet draining into a franchise model. Anyone with a phishing campaign and a few hundred dollars can become a crypto criminal. This scale is what makes the problem so difficult to solve.

Detection is possible but hard. Many attacks leave no blockchain signature. Most attacks are indistinguishable from normal user behaviour. And the speed of the ecosystem means new tools and evasion techniques emerge constantly.

The path forward requires three things. First, better security practices from users. Hardware wallets and strong passphrases are not sexy, but they work. Second, better tooling from exchanges and custodians. Withdrawal limits, address whitelisting, and outgoing transaction monitoring can block many attacks. Third, continued law enforcement and intelligence work to disrupt the most profitable operations.

SOS Intelligence will continue monitoring these threats. We will continue indexing dark web marketplaces and tracking the money laundering pipelines. We will continue alerting our customers when we identify attacks targeted at their users. And we will continue building the tools that make attribution and defence possible.

Appendix: DARKSEARCH Observed Listings

Between February 2026 and March 2026, our DARKSEARCH crawlers observed the following active marketplace listings offering cryptocurrency fraud tools and services. All onion URLs are defanged to prevent accidental access.

External References

This report draws on the following open-source intelligence and blockchain security research:

  • Chainalysis (2025). 2025 Crypto Crime Report. Available at: https://www.chainalysis.com/reports/crypto-crime-report-2025/. Documents wallet drainer losses exceeding $500 million in 2024; tracks drainer family evolution and exit patterns.
  • ScamSniffer (2024-2026). Wallet Drainer Tracking. Available at: https://scamsniffer.io. Real-time tracking of Angel Drainer, Inferno Drainer, and Pink Drainer operational signatures across blockchain transactions.
  • SlowMist (2024-2026). Blockchain Security Research. Available at: https://slowmist.medium.com. Technical analysis of wallet drainer mechanics, transaction patterns, and operational security.
  • Elliptic (2024-2026). Blockchain Analytics Research. Available at: https://www.elliptic.co. Tracks money laundering pipelines, privacy coin conversions, and OTC broker involvement in stolen funds movement.
  • FBI IC3 (2024). Internet Crime Complaint Center – Cryptocurrency Fraud Statistics. Available at: https://ic3.gov. Official statistics on reported cryptocurrency fraud, wallet draining, and wallet compromise cases.
  • Atomic Wallet Security Incident (June 2023). Initial reports and analysis of $35 million hack attributed to Lazarus Group; tracked credential circulation on dark web marketplaces through 2026.
  • MITRE ATT&CK Framework. Cryptocurrency Fraud Tactics. Documents attack patterns including credential dumping (T1005), phishing for information (T1598), and signed script proxy execution (T1216).

Header image by Art Rachen on Unsplash

Wallet by Emil Kalibradov on Unsplash

Drain by Daniel Dan on Unsplash

Casino by Michał Parzuchowski on Unsplash
"SOS
Investigation, Opinion

Emoji Smuggling: Hiding Malicious Code in Plain Sight

Emoji smuggling represents an emerging obfuscation technique where attackers exploit Unicode encoding and emoji characters to conceal malicious code, bypass security filters, and evade detection systems. Whilst it may sound whimsical, this attack vector leverages legitimate Unicode functionality to create serious security challenges for organisations. Understanding how attackers weaponise these seemingly innocent characters helps us build better defences and recognise when something suspicious might be happening.

This post explores what emoji smuggling is, how attackers use it, and what organisations can do to protect themselves.

The Foundation: How Text Actually Works

Before we dive into the attack itself, we need to understand something fundamental about how computers handle text. When you type a letter, number, or emoji, your computer doesn’t actually store that visual symbol. Instead, it stores a number that represents that character. This system is called Unicode, and it’s what allows your computer to display everything from English letters to Chinese characters to emoji.

For example, when you use the fire emoji 🔥, your computer stores it as the number U+1F525. Every character you can type has its own unique number in the Unicode system. This is brilliant for international communication, but it also creates opportunities for attackers.

The key insight is this: many security systems were built to look for suspicious patterns in regular letters and numbers, but they often don’t scrutinise emoji and special Unicode characters as carefully. Attackers exploit this gap.

What Is Emoji Smuggling?

Emoji smuggling is the practice of using emoji, special Unicode characters, or look-alike characters to hide malicious content from security systems while keeping it functional for their purposes. Think of it as writing a secret message in invisible ink that only becomes visible when you want it to.

Attackers use several techniques:

Look-Alike Characters: Some characters from different alphabets look identical to English letters but are technically different. For instance, the Cyrillic letter ‘а’ looks exactly like the English ‘a’, but computers see them as completely different characters. An attacker might register a domain like “pаypal.com” (using a Cyrillic ‘а’) that looks legitimate to humans but directs to a phishing site.

Emoji as Code: This technique involves creating a substitution cypher where each emoji represents a command, function, or piece of data. Attackers establish a mapping system, similar to how spies might use a codebook. For example, they might decide that:

  • 🔥 represents “delete”
  • 📁 represents “file”
  • 🌐 represents “download”
  • 💀 represents “execute”

So a string like “🔥📁🌐💀” would decode to “delete file, download, execute”. To anyone glancing at log files or monitoring network traffic, this looks like someone simply sent some emoji in a message. Security systems scanning for dangerous keywords like “delete”, “execute”, or suspicious command patterns won’t flag it because they’re looking for text, not pictures.

The attacker’s malware or script includes a decoder that translates these emoji back into actual commands when executed. What makes this particularly effective is that emojis feel innocuous. We’re used to seeing them in messages and social media, so their presence doesn’t immediately raise suspicion the way a long string of seemingly random characters might.

Consider a real scenario: an attacker gains limited access to a system and needs to communicate instructions to their malware without triggering security alerts. They might send what appears to be a harmless message containing emojis through a chat system or email. The malware on the compromised system receives this message, decodes the emoji, and executes the hidden commands. To security analysts reviewing logs, it simply looks like someone sent some emoji.

Invisible Characters: This is perhaps the most insidious technique because it exploits characters you literally cannot see. Unicode includes several characters that have zero width, meaning they take up no visual space on screen. These include the Zero-Width Space (U+200B), Zero-Width Non-Joiner (U+200C), and Zero-Width Joiner (U+200D).

Here’s how this works in practice. Imagine a security system is configured to block any script that contains the text string “malicious_function”. An attacker can break up this string by inserting zero-width characters between the letters:

What you see: malicious_function()
 What’s actually there: mal​ici​ous_​fun​cti​on() (contains invisible zero-width spaces)

To the human eye, even if you’re carefully reading through code, these look identical. But to a security scanner looking for the exact string “malicious_function”, the second version doesn’t match because those invisible characters break up the pattern. The scanner sees “mal[invisible]ici[invisible]ous[invisible]_fun[invisible]cti[invisible]on” and doesn’t recognise it as a threat.

However, when this code actually runs, many programming languages and interpreters ignore these zero-width characters during execution. The invisible spaces are stripped out, and the function executes normally. So the attacker has successfully hidden their malicious code from security scans whilst maintaining its functionality.

Attackers also use invisible characters to hide data within seemingly innocent text. Imagine you’re trying to smuggle a password out of a secure system. You could write a normal-looking sentence like “Please review the quarterly report”, but encode the password in invisible characters interspersed throughout. To anyone reading it, it’s just a mundane sentence. But someone with the right decoder can extract the hidden information.

This technique is particularly dangerous because it’s virtually impossible to detect through visual inspection alone. You need specialised tools that reveal invisible characters, and even then, you need to know how to look for them.

Direction Trickery: Unicode includes special characters that change the direction text flows (needed for languages like Arabic). Attackers use these to make filenames appear safe when they’re actually dangerous. A file might display as “document.txt” but actually be “tnemucod.exe” with a direction-reversal character hiding the true extension.

Why This Works

You might wonder why this is effective if it seems so simple. The answer lies in how security systems are designed.

Most security tools were built to detect patterns in regular ASCII text (the basic English letters, numbers, and symbols). They look for suspicious keywords, known malicious code patterns, or dangerous file types. But when attackers encode their attacks using Unicode tricks, these patterns become unrecognisable to the security system.

It’s similar to how a metal detector at an airport won’t find a ceramic knife. The detector is designed to find metal, and the knife is dangerous, but because it’s made of the wrong material, it slips through. Similarly, security filters are often designed to catch ASCII-based threats, so Unicode-based threats slip through.

Additionally, completely blocking Unicode would break legitimate functionality. Businesses operate globally, users have names in different languages, and emojis are a standard part of modern communication. Security teams can’t simply ban all non-English characters without severely impacting usability.

Real-World Examples

Understanding the theory is one thing, but seeing how this plays out in practice makes the threat more tangible.

Phishing Attacks: Attackers register domain names using look-alike characters. A company email might tell you to log in at “microṡoft.com” (note the dot over the ‘s’). To most people, this looks perfectly normal, but it’s not the real Microsoft. Users enter their credentials, and the attacker now has access to their account.

Bypassing Content Filters: Many organisations block certain words in emails or messages to prevent data leaks or inappropriate content. An employee trying to circumvent these filters might write “pаssword” using a Cyrillic ‘а’ instead of the English ‘a’. The filter doesn’t catch it because it’s technically a different word, but humans reading it understand the meaning perfectly.

Hidden Data Exfiltration: An attacker who has compromised a system needs to send stolen data out without triggering data loss prevention systems. They might encode credit card numbers using emoji: “4️⃣5️⃣3️⃣2️⃣ 1️⃣2️⃣3️⃣4️⃣ 5️⃣6️⃣7️⃣8️⃣ 9️⃣0️⃣1️⃣0️⃣”. Security systems looking for the pattern of a 16-digit number won’t detect this, but it’s trivial to decode on the other end.

Malware Obfuscation: Malware authors need to hide suspicious commands from antivirus software. They might write “po​we​rs​he​ll” with invisible zero-width spaces between letters. When a security researcher looks at the code, they see gibberish, and antivirus scans don’t recognise the command. But when the malware runs, it successfully executes PowerShell commands.

Code Injection: Web applications that don’t properly handle Unicode input can be vulnerable to injection attacks. An attacker might submit what looks like normal text but includes hidden direction-control characters that manipulate how the input is processed, potentially executing unauthorised database queries or commands.

The Impact on Large Language Models

As artificial intelligence and large language models (LLMs) become increasingly integrated into business operations and security workflows, emoji smuggling presents a unique and evolving challenge. These AI systems, designed to understand and process human language, can be vulnerable to Unicode-based attacks in ways that differ from traditional security systems.

Prompt Injection via Unicode: LLMs process text input and generate responses based on their training. Attackers can use Unicode tricks to bypass safety filters or inject malicious instructions that the model follows. For instance, an attacker might use invisible characters to break up prohibited phrases that the model has been trained to refuse, or use look-alike characters to make harmful instructions appear benign to content filters whilst remaining interpretable by the model.

Consider a scenario where an LLM-powered chatbot has been instructed never to provide information about bypassing security systems. An attacker might craft a prompt using Cyrillic characters that visually spell out the forbidden request but technically use different Unicode characters. The safety filter checking for specific English phrases might not catch it, but the LLM, trained on diverse text including multiple alphabets, might still understand and respond to the request.

Training Data Poisoning: If emoji-encoded malicious content makes it into an LLM’s training data, the model might learn to recognise and even replicate these encoding schemes. This could result in the model inadvertently helping attackers by generating emoji-encoded malicious payloads or failing to recognise them as threats when analysing suspicious content.

Context Window Manipulation: LLMs have limited context windows (the amount of text they can process at once). Attackers can use invisible Unicode characters to pad inputs, pushing important safety instructions or system prompts out of the model’s effective context whilst keeping malicious instructions within it. The model might then follow attacker instructions without the safeguards that should be governing its behaviour.

Output Encoding Attacks: Even if an LLM correctly identifies malicious content, attackers can request that the output be encoded using emoji or Unicode tricks. The model might comply, creating encoded malicious payloads that bypass downstream security filters. For example, asking an LLM to “translate this command into emoji” could result in the creation of an emoji-based encoding scheme that evades detection.

Jailbreaking and Safety Bypass: The LLM security community has documented numerous “jailbreaking” techniques where carefully crafted prompts cause models to ignore their safety training. Unicode tricks add another dimension to this. Attackers can use direction override characters, invisible spaces, or homoglyphs to craft prompts that appear innocent to automated safety systems but contain hidden instructions that the LLM interprets and follows.

Challenges for AI Security Teams: Defending LLMs against emoji smuggling is particularly challenging because these models are designed to be flexible and understand context across languages and writing systems. Blocking all Unicode would severely limit their utility for international users. Instead, organisations deploying LLMs need to:

  • Implement robust input normalisation before text reaches the model
  • Use multiple layers of content filtering that account for Unicode variations
  • Monitor model outputs for unusual Unicode patterns that might indicate encoding attempts
  • Regularly test models with Unicode-based attack vectors
  • Maintain updated safety training that includes awareness of these techniques

The Detection Problem: Traditional security tools can be configured to flag invisible characters or suspicious Unicode patterns. However, LLMs are probabilistic systems that generate novel outputs. This makes it harder to predict when they might be manipulated into producing emoji-encoded content or responding to Unicode-obfuscated instructions. Security teams need to think about both preventing malicious inputs and detecting problematic outputs.

Real-World Implications: As organisations increasingly rely on LLMs for tasks like code generation, content moderation, customer service, and security analysis, the stakes grow higher. An LLM that can be tricked into generating malicious code through Unicode manipulation, or that fails to identify emoji-smuggled threats in content it’s supposed to be moderating, becomes a liability rather than an asset.

The intersection of emoji smuggling and LLM security represents an emerging area of concern. As these AI systems become more capable and more widely deployed, attackers will continue to probe for weaknesses in how they handle Unicode and interpret encoded content. Organisations must stay vigilant and ensure their AI security strategies account for these evolving threats.

The Challenge for Defenders

Defending against emoji smuggling is tricky because it requires balancing security with functionality. Organisations face several challenges:

International Requirements: Businesses serve global customers and employ international staff. Blocking non-English characters would prevent people from using their actual names or communicating in their native languages. This isn’t just inconvenient; in many jurisdictions, it could be discriminatory.

Performance Concerns: Thoroughly inspecting every character of every piece of text for Unicode tricks requires significant computing power. For high-traffic websites or applications, this can slow things down noticeably.

Evolving Techniques: The Unicode standard contains over 140,000 characters and is regularly updated. Attackers constantly find new, creative ways to exploit this complexity. What works to block attacks today might not catch the techniques used tomorrow.

False Positives: Aggressive filtering can block legitimate content. An email from a Greek customer with a name containing Greek letters might be flagged as suspicious. A message containing many emojis (completely normal in casual conversation) might trigger alerts.

Defensive Strategies

Despite these challenges, organisations can implement effective defences against emoji smuggling. The key is taking a layered approach rather than relying on any single solution.

Input Validation and Normalisation: Systems should normalise Unicode input, converting visually similar characters to a standard form. This helps ensure that “pаypal” (with a Cyrillic ‘а’) and “paypal” (with an English ‘a’) are recognised as attempts to use the same string. For structured data like usernames or email addresses, systems can enforce stricter rules about which characters are allowed.

Context-Aware Security: Different fields need different levels of restriction. A username field might only allow basic English letters and numbers, whilst a comment field can permit a wider range of characters, including emojis. Security controls should adapt to the context rather than applying blanket rules.

Visual Similarity Detection: Advanced systems can detect when Unicode characters are being used to mimic legitimate domains or brands. If someone tries to register a domain that looks almost identical to a major company’s website, the system can flag it for review.

Invisible Character Removal: For most applications, there’s no legitimate reason to include invisible Unicode characters in structured data. Systems can strip these out or flag their presence as suspicious, particularly in fields like usernames, file names, or code inputs.

Monitoring and Anomaly Detection: Rather than trying to block everything suspicious at the gate, organisations can monitor for unusual patterns. A sudden spike in emoji usage in log files, the presence of mixed alphabets in a single field, or zero-width characters appearing in database entries can all trigger alerts for security teams to investigate.

User Education: Technical controls only go so far. Training staff to recognise suspicious URLs (by checking the actual address in their browser, not just what’s displayed), to be cautious about unexpected login requests, and to report unusual behaviour helps catch attacks that slip through automated defences.

Security by Design: When building new systems, developers should consider Unicode handling from the start. This includes using libraries that properly handle normalisation, implementing appropriate validation for each input field, and testing with Unicode attack vectors during security assessments.

What This Means for Different Audiences

For Security Professionals: Emoji smuggling should be part of your threat model. Include Unicode-based attacks in penetration testing, ensure your security tools can detect these techniques, and review how your applications handle Unicode input. This isn’t a theoretical concern; it’s being actively exploited.

For Developers: Don’t assume that checking for suspicious ASCII strings is sufficient. Implement proper Unicode normalisation, validate input based on context, and be aware of how your programming language and frameworks handle Unicode. What you see on screen may not be what’s actually stored or processed.

For Business Leaders: Understand that security isn’t just about detecting known malware signatures or blocking obvious threats. Modern attacks exploit subtle aspects of how systems work. Investment in security tools, training, and secure development practices pays dividends by preventing breaches that could damage reputation and finances.

For Everyday Users: Be sceptical of links, even if they look legitimate. When entering sensitive information, double-check that you’re on the correct website by examining the URL carefully. Be particularly cautious with messages that create urgency or ask you to log in via a provided link.

The Bigger Picture

Emoji smuggling is part of a broader category of attacks that exploit the gap between human perception and machine processing. We see what we expect to see, whilst computers process what’s actually there. Attackers exploit this disconnect.

This isn’t unique to Unicode. Similar principles apply to audio deepfakes (where we hear what sounds like a trusted voice), visual manipulations (where images appear legitimate but are fabricated), and social engineering (where contexts appear trustworthy but are manufactured). The common thread is exploiting trust and perception.

As systems become more sophisticated, so do attacks. The growth of international internet usage and the ubiquity of emoji in modern communication create both opportunities and challenges. We need security solutions that protect without stifling legitimate use, that adapt to new threats whilst maintaining usability, and that account for the complexity of human language and communication.

Conclusion

Emoji smuggling demonstrates that security threats don’t always come from sophisticated zero-day exploits or advanced persistent threats. Sometimes they come from clever misuse of legitimate functionality. A simple emoji or an invisible character can bypass expensive security systems if those systems aren’t designed to handle them.

The good news is that awareness and proper design can mitigate these risks. Organisations that understand the threat, implement appropriate controls, and maintain vigilance can protect themselves effectively. It requires thinking beyond traditional security approaches and considering how attackers might abuse features we take for granted.

As you think about your own organisation’s security, consider asking: How do our systems handle Unicode? Could someone use look-alike characters to impersonate our brand? Are we monitoring for unusual patterns in text input? Could malicious code be hiding in emojis or invisible characters?

These questions might reveal gaps in your defences, but identifying those gaps is the first step towards closing them. In security, the threats we understand and prepare for are far less dangerous than the ones we overlook.

Smiling emoji image photo by chaitanya pillala on Unsplash.

Header image photo by Shubham Dhage on Unsplash.

"SOS
SOS Intelligence Webinar

SOS Intelligence platform updates and roadmap for 2026 webinar

Can you believe a month has already past this year?! Join us on February 12th at 1.30pm to learn about the updates that we have made for the SOS Intelligence platform plus a peek into what is planned in the coming months.

What we will discuss:

  • AI Analyst
  • CVE Intelligence
  • Telegram Research

Hosted by Jon Moss with SOS Intelligence Founder and CEO, Amir Hadzipasic and Threat Intelligence Analyst Daniel Collyer.

Sign up to the webinar to receive a recording via email if you cannot attend on the day. By signing up you will also receive our newsletter for future events. You can always unsubscribe with one click.

Looking forward to seeing you!

Stay safe,

Amir

""/
Investigation, Opinion

Key Cyber Threat Intelligence Trends to Watch in 2026

Why 2026 Matters for CTI

As organisations enter 2026, cyber threat intelligence finds itself at a critical inflexion point. The threat landscape continues to expand in volume and complexity, but the pressures shaping it are no longer purely technical. Geopolitical instability, regional conflict, and sustained economic uncertainty are increasingly influencing who is targeted, why, and to what end. For businesses, this means cyber risk is now inseparable from broader strategic and operational risk.

At the same time, the pace of technological change continues to accelerate. Artificial intelligence is now firmly embedded on both sides of the threat equation. Adversaries are using AI to scale social engineering, automate reconnaissance, and rapidly adapt tooling, while defenders are racing to apply the same technologies to detection, analysis, and response. This arms race is generating more data, more alerts, and more intelligence than ever before.

Yet quantity is no longer the problem. Many organisations are experiencing intelligence overload, where feeds, reports, and indicators accumulate faster than they can be meaningfully consumed. Decision makers are not asking for more information, but for clearer insight. They want to understand which threats matter, how they are likely to manifest, and what actions should be prioritised in response.

As a result, 2026 represents a decisive shift for cyber threat intelligence. The focus is moving away from collecting more data and towards understanding it better. Success is increasingly defined by context, relevance, and the ability to translate technical detail into actionable judgment. This is less a year of entirely new threats and more a year defined by how existing threats are used, scaled, and adapted to specific targets and circumstances.

In this article, we explore the key trends shaping cyber threat intelligence in 2026, and what they mean for organisations seeking to make informed, risk-based decisions in an increasingly uncertain environment.

AI-Native Threat Actors Become the Norm

By 2026, the use of artificial intelligence by threat actors can no longer be described as experimental or emerging. For many adversaries, AI-enabled tooling is now embedded into everyday operations, shaping how attacks are planned, executed, and refined. Rather than creating entirely new categories of threats, AI is amplifying existing ones by increasing their speed, scale, and apparent sophistication.

One of the most visible impacts is in phishing, pretexting, and broader social engineering activity. AI-generated content allows attackers to produce convincing messages tailored to specific organisations, roles, or even individuals with minimal effort. Language quality is no longer a reliable signal of legitimacy, and pretexts can be rapidly adapted based on open source information, previous engagement, or real-time feedback. This has significantly reduced the cost and skill barrier traditionally associated with effective social engineering.

Malware development has also been accelerated. AI-assisted coding and analysis tools enable faster iteration, allowing threat actors to modify payloads, obfuscation techniques, and delivery mechanisms in near real time. Polymorphism and frequent recompilation mean that identical samples may exist only briefly, limiting the usefulness of traditional signature-based detection and static file indicators. The result is a faster-moving malware ecosystem that is harder to catalogue and track using conventional methods.

Reconnaissance and target profiling are increasingly automated. Threat actors can now use AI to process large volumes of leaked data, scraped content, and technical metadata to identify high-value targets and likely points of weakness. This automation enables more precise targeting while reducing the need for manual research, allowing even smaller or less experienced groups to operate with a level of efficiency previously associated with more capable actors.

Taken together, these developments are blurring traditional distinctions between high-skill and low-skill adversaries. Tools that once required significant expertise to develop or operate are becoming accessible through automation and commoditised services. As a result, lower capability actors can conduct campaigns that appear more polished, more targeted, and more persistent than their underlying skill level would suggest.

For cyber threat intelligence teams, this shift has important implications. Static indicators such as file hashes, domains, and IP addresses are ageing even faster than before, often becoming obsolete within hours or days. While such indicators still have operational value, they can no longer be the primary lens through which AI-enabled activity is understood.

Instead, there is a growing need to focus on behavioural patterns and campaign-level analysis. Understanding how attacks are structured, how lures evolve over time, and how infrastructure is deployed and rotated provides more durable insight than individual technical artefacts. Equally important is tracking the evolution of tradecraft. The key intelligence question is no longer which tool was used, but how it was applied, adapted, and combined with other techniques to achieve an objective.

In 2026, effective threat intelligence depends less on cataloguing tools and more on recognising patterns of behaviour. As AI continues to level the playing field for adversaries, the ability to identify and contextualise these patterns will be central to maintaining meaningful visibility into the threat landscape.

AI-Enabled Tradecraft in Practice

During 2024 and 2025, security researchers documented the use of generative AI tools such as WormGPT and FraudGPT in live phishing and business email compromise campaigns, enabling fluent, highly targeted lures at scale. Microsoft and Google both reported attackers using AI-assisted reconnaissance to tailor phishing based on user roles, organisations, and cloud environments. In parallel, Mandiant and Microsoft observed identity-focused intrusions where domains, payloads, and malware variants rotated faster than traditional indicators could be operationalised. While static indicators decayed rapidly, behavioural patterns such as role-based targeting, cloud-hosted delivery, MFA abuse, and living-off-the-land activity remained consistent.

Content and Format Abuse Outpaces Traditional Detection

As technical controls continue to improve, threat actors are increasingly shifting their focus away from exploiting software vulnerabilities and towards abusing trust in common content formats. By 2026, malicious activity is frequently concealed within files and data types that organisations are structurally inclined to allow, inspect lightly, or prioritise for usability over security.

Content-type smuggling and polyglot files are becoming more prevalent as attackers exploit discrepancies between how systems interpret file formats. A single file may present itself as benign to one control while being parsed differently by another, allowing embedded scripts or payloads to execute downstream. These techniques are not new, but they are now being applied more systematically and at greater scale, particularly in environments that rely on automated content handling.

Common formats such as PDFs, images, emojis, markdown, and compressed archives are increasingly abused as delivery vehicles. PDFs can carry embedded scripts or external references, images can contain hidden data or exploit parsing behaviour, and text-based formats can be manipulated to trigger unexpected interpretation by browsers, email clients, or automated analysis tools. Even elements designed for expression and accessibility, such as emojis, can be repurposed to carry hidden instructions or evade simple content inspection.

Delivery mechanisms are also evolving. Rather than relying solely on direct email attachments or malicious links, attackers are increasingly using trusted SaaS platforms and collaboration tools to distribute payloads. File sharing services, document collaboration platforms, and messaging tools provide a level of implicit trust and are often deeply integrated into business workflows. This makes it harder for both users and security controls to distinguish malicious activity from legitimate use.

These techniques are particularly effective at evading gateway and sandbox-based detection. Many security controls are optimised to analyse standalone files or clearly defined executables, not content that only becomes malicious when rendered in a specific context or combined with user interaction. Sandboxes may fail to replicate the precise conditions required to trigger malicious behaviour, while gateways may prioritise performance over deep inspection of complex or nested formats.

For cyber threat intelligence teams, this trend reinforces the importance of tracking delivery mechanisms as a primary tactic, technique, and procedure. Understanding how malicious content is introduced into an environment often provides more durable insight than focusing solely on the final payload. The same malware family may be delivered through multiple formats and channels, each tailored to exploit specific organisational habits or control gaps.

This also highlights the intelligence value of analysing how malware arrives, not just what it is. Patterns in file types, hosting platforms, and user interaction requirements can reveal actor preferences and campaign objectives that are not visible through static analysis alone. Such insights are particularly valuable for informing detection engineering and user awareness efforts.

Finally, this trend underscores the need for stronger collaboration between cyber threat intelligence teams and email and web security functions. Intelligence on emerging delivery techniques must be translated into practical guidance for those configuring and tuning controls. In 2026, effective defence against content and format abuse depends not only on identifying malicious artefacts, but on understanding and disrupting the pathways through which they are delivered.

Abuse of Trusted Formats and Platforms

During 2023–2025, multiple security vendors reported widespread abuse of PDFs and archive files to deliver malware while bypassing email and web gateways, including campaigns where malicious content was only revealed after user interaction. Microsoft and Google both documented attackers hosting payloads on legitimate SaaS platforms such as OneDrive, Google Drive, and Dropbox, exploiting implicit trust and integration with enterprise environments. Researchers also observed the use of HTML smuggling and polyglot files to evade content inspection by disguising executable behaviour within allowed formats. In many cases, sandbox detonation failed to trigger malicious activity due to environmental checks or delayed execution. These campaigns demonstrated that the most reliable intelligence signal was not the final payload, but the consistent delivery techniques and abuse of trusted platforms, reinforcing the value of tracking delivery mechanisms as a primary tactic.

The Continued Rise of Identity-Centric Attacks

The Continued Rise of Identity-Centric Attacks

As organisations continue to adopt cloud services and remote working models, identity has become the primary control plane for access to systems and data. In 2026, attackers are increasingly targeting identity directly, recognising that compromising credentials or sessions often provides broader and more durable access than exploiting a single technical vulnerability.

One of the most common techniques remains multi-factor authentication fatigue, often referred to as push bombing. By repeatedly triggering authentication prompts, attackers aim to exploit user frustration or inattention, eventually inducing approval of a fraudulent request. While awareness of this technique has grown, it remains effective in environments where controls are permissive or user training is inconsistent.

Token theft and session hijacking are also becoming more prevalent. Rather than capturing usernames and passwords, attackers increasingly seek to obtain valid session tokens, cookies, or authentication artefacts that allow them to bypass interactive login processes altogether. These techniques are particularly effective against cloud services and single sign-on environments, where a compromised token can provide access to multiple applications without further challenge.

The abuse of OAuth applications and cloud identities represents another significant area of risk. Malicious or compromised OAuth apps can be granted persistent access to user data and resources, often with limited visibility once approved. Attackers may also create or manipulate cloud-native identities, such as service principals or managed identities, to establish long-term access that blends into normal administrative activity.

Once access is obtained, many adversaries favour living-off-the-land techniques within cloud environments. By using legitimate tools, built-in administrative functions, and native APIs, attackers can move laterally, escalate privileges, and exfiltrate data while minimising the use of overtly malicious tooling. This approach reduces the likelihood of triggering traditional malware-focused detection and allows activity to appear operationally routine.

For cyber threat intelligence teams, these developments necessitate a shift in focus. Traditional indicators such as IP addresses and domains remain relevant, but they provide limited insight into identity-centric attacks that leverage legitimate infrastructure and services. Greater value lies in understanding patterns of authentication abuse, anomalous access behaviour, and misuse of identity features.

Tracking actor playbooks against identity and access management controls is becoming increasingly important. Intelligence that maps how specific adversaries exploit MFA configurations, token lifetimes, OAuth consent processes, or role assignment models can directly inform defensive priorities. This enables organisations to move beyond generic hardening guidance and focus on the controls most likely to be targeted.

In 2026, effective threat intelligence plays a critical role in shaping identity defence. By translating observed attack patterns into concrete recommendations, CTI teams can help organisations prioritise identity hardening efforts and reduce exposure at what has become the most frequently attacked layer of the modern enterprise.

Identity as the Primary Attack Surface

Between 2023 and 2025, Microsoft, Mandiant, and Okta documented a sustained rise in identity-centric intrusions involving MFA fatigue attacks, token theft, and session hijacking, particularly against cloud-first organisations. Campaigns attributed to financially motivated groups showed repeated push bombing attempts followed by abuse of valid sessions rather than credential reuse. Researchers also reported widespread misuse of OAuth applications, where attackers gained persistent access by tricking users into granting permissions to malicious or compromised apps. Once inside, adversaries frequently relied on living-off-the-land techniques, using native cloud tooling and APIs to blend into normal administrative activity. These cases highlighted the limited value of traditional IP- or domain-based indicators and reinforced the importance of tracking identity behaviour and attacker playbooks against IAM controls.

Ransomware Becomes a Business Model, Not a Malware Type

Ransomware Becomes a Business Model, Not a Malware Type

By 2026, ransomware will be best understood not as a single category of malware, but as a service-driven business model. The technical payload used to encrypt systems is often interchangeable, while the real differentiation lies in how operations are organised, monetised, and sustained. This shift continues to reshape both the threat landscape and the way organisations should approach ransomware risk.

Ransomware-as-a-service ecosystems continue to evolve and mature. Core developers provide tooling, infrastructure, and branding, while affiliates conduct intrusions and deploy payloads in exchange for a share of the proceeds. This model allows rapid scaling, frequent rebranding, and the replacement of disrupted components with minimal impact to overall activity. It also creates a steady flow of new and short-lived variants that complicate traditional tracking.

At the same time, ransomware operations are increasingly decoupled from encryption itself. Data theft and extortion-only models remain prevalent, particularly where reliable backups or operational resilience reduce the impact of encryption. Many campaigns now combine multiple pressure points, including data leaks, regulatory exposure, and direct contact with customers or partners. These hybrid approaches are designed to maximise leverage while reducing technical complexity.

Rebranding and fragmentation further obscure attribution. Groups regularly change names, infrastructure, and public-facing personas in response to law enforcement action or reputational damage. In some cases, operators deliberately adopt the branding or tactics of other groups to mislead victims and researchers. False-flag activity adds further noise, making it difficult to draw conclusions based solely on malware samples or ransom notes.

Targeting is also shifting. While large enterprises remain attractive, mid-sized organisations are increasingly in focus due to perceived gaps in security maturity and incident response capability. Supply chains continue to present valuable opportunities, allowing attackers to leverage trusted relationships to increase reach and impact. These campaigns often prioritise speed and disruption over long-term persistence.

For cyber threat intelligence teams, these trends present both challenges and opportunities. Actor clustering becomes more difficult as tooling and branding fragment, but it also becomes more valuable. Understanding how campaigns relate to one another through shared behaviours, infrastructure management, and operational patterns provides insight that individual malware labels cannot.

This reinforces the need to focus on who is behind an operation rather than which strain is used. Tracking negotiation behaviour, communication style, leak site activity, and pressure tactics can reveal consistent operator fingerprints even as technical components change. Such intelligence is particularly valuable for incident response planning, negotiation strategy, and executive decision-making.

In 2026, effective ransomware intelligence depends on moving beyond file-based analysis and towards a deeper understanding of adversary operations as businesses in their own right. Those who can identify and anticipate how these businesses operate are better positioned to disrupt them and reduce their impact.

Ransomware as an Operational Business

From 2023 to 2025, ransomware groups such as LockBit, ALPHV, and Cl0p were repeatedly observed operating as service-based ecosystems, with affiliates conducting intrusions while core teams managed tooling, infrastructure, and leak sites. High-profile campaigns, including the MOVEit and GoAnywhere mass exploitation events, demonstrated how data theft and extortion could be conducted at scale without relying solely on encryption. Researchers also documented frequent rebranding and fragmentation following law enforcement pressure, complicating attribution based on malware families alone. Across these campaigns, consistent behaviours such as negotiation style, leak site structure, and pressure tactics persisted even as payloads and infrastructure changed. These patterns underscore the value of actor-centric intelligence focused on who is operating, rather than which ransomware strain is deployed.

Geopolitics Drives Threat Actor Priorities

Geopolitics Drives Threat Actor Priorities

In 2026, the influence of geopolitics on the cyber threat landscape is more pronounced than ever. Nation-state and state-aligned actors are not only increasing in activity but are also shaping the broader ecosystem in which financially motivated and ideologically driven groups operate. Cyber operations are now a routine extension of geopolitical competition, conflict, and signalling.

One key trend is the spillover of geopolitical tensions into cyberspace. Regional conflicts, diplomatic disputes, and economic sanctions frequently coincide with surges in cyber activity, ranging from espionage and influence operations to disruptive attacks. These campaigns may not always be directly attributable to a single state, but they often align closely with national interests or strategic objectives.

Critical infrastructure and logistics networks are increasingly attractive targets. Energy, transport, telecommunications, and supply chain management systems offer opportunities for intelligence collection, disruption, and strategic pressure. Even limited or short-lived interference can have outsized economic and political effects, making these sectors a persistent focus for capable adversaries.

Hacktivism continues to play a prominent role, often blurring the boundary between grassroots activism and state-aligned activity. In some cases, hacktivist groups act as proxies or amplifiers, conducting operations that provide plausible deniability while supporting broader strategic aims. In others, state actors deliberately mimic hacktivist tactics to obscure attribution and complicate response decisions.

These dynamics contribute to increasingly blurred lines between cybercrime, espionage, and disruption. Financially motivated groups may be tolerated or tacitly supported when their activity aligns with national interests, while espionage operations may incorporate criminal techniques or infrastructure. This convergence makes simple categorisation of threats less meaningful and increases the risk of misinterpretation.

For cyber threat intelligence teams, this environment elevates the importance of strategic intelligence alongside tactical reporting. Understanding the geopolitical context in which activity occurs is often essential to interpreting intent, likely targets, and potential escalation. Mapping geopolitical events to observed cyber activity can help organisations anticipate periods of heightened risk and adjust their posture accordingly.

Equally important is the ability to communicate uncertainty and intent to leadership. Strategic intelligence rarely offers definitive answers, but it can provide informed assessments and plausible scenarios. In 2026, effective CTI is measured not only by technical accuracy but by its ability to support informed decision-making in a world where cyber activity is increasingly intertwined with global politics.

Geopolitics Shaping Cyber Operations

Between 2022 and 2025, geopolitical events including the war in Ukraine and heightened tensions in the Middle East coincided with spikes in cyber activity targeting government, energy, logistics, and telecommunications sectors. Security firms and government agencies reported coordinated campaigns involving espionage, disruption, and influence operations aligned with national interests. Hacktivist groups emerged rapidly around these conflicts, often amplifying or obscuring state-aligned activity through defacements, data leaks, and denial-of-service attacks. In several cases, financially motivated and politically aligned operations used overlapping infrastructure and techniques, blurring traditional threat categories. These trends highlighted the growing importance of strategic intelligence that links geopolitical developments to cyber activity and communicates intent and uncertainty to decision-makers.

Intelligence Consumers Demand Clarity, Not Just Alerts

Intelligence Consumers Demand Clarity, Not Just Alerts

As cyber threat intelligence becomes more widely consumed across organisations, expectations around how intelligence is delivered are evolving. In 2026, the challenge is no longer access to threat data, but ensuring that alerts and intelligence are timely, relevant, and actionable for their intended audience.

Security teams and decision makers are exposed to a growing volume of alerts, notifications, and intelligence updates. While this flow of information is essential for maintaining situational awareness, it can become difficult to distinguish between background noise and issues that require immediate attention. This has led to increasing demand for clarity alongside coverage.

Rather than simply asking what has been observed, intelligence consumers are asking more targeted questions. They want to understand why an alert matters, how it relates to their environment, and what actions should be considered next. Alerts that are enriched with context, confidence, and clear analytical judgment are far more likely to drive effective response than raw signals alone.

This has reinforced the importance of tying intelligence to risk and impact. When alerts are mapped to threat actors, campaigns, targeting patterns, or likely objectives, they become easier to prioritise and act upon. Intelligence that highlights relevance, such as sector targeting, geographic focus, or alignment with known tradecraft, enables organisations to make faster and more informed decisions.

Narrative also plays an increasingly important role. Even within alert-driven systems, structured explanations and concise assessments help consumers interpret activity and avoid misreading its significance. The ability to combine timely alerting with clear analytical framing is becoming a key differentiator in intelligence delivery.

For CTI providers, this reflects a broader maturity shift from delivering data alone to delivering understanding at scale. Alerts remain a critical mechanism for awareness and response, but their value is maximised when they are supported by consistent analysis and clear articulation of what the intelligence means. In 2026, the most effective intelligence services are those that help customers move confidently from notification to decision.

CTI Tooling Consolidation, Integration, and Automation

The CTI tooling landscape continues to evolve as organisations seek to simplify workflows and extract greater value from the intelligence they consume. By 2026, many teams are consolidating platforms and prioritising solutions that integrate cleanly into existing security operations rather than operating in isolation.

Overlapping tools and fragmented intelligence sources can make it difficult to maintain a coherent view of the threat landscape. As a result, there is growing emphasis on platforms and services that centralise intelligence, reduce duplication, and present information in a consistent and usable format. Integration with SIEM, SOAR, EDR, and email security tooling is increasingly expected rather than optional.

Automation plays a central role in enabling this consolidation. Automated enrichment, correlation, and triage allow large volumes of intelligence to be processed and surfaced rapidly. This is particularly important for alert-driven intelligence delivery, where speed and scale are critical. Automation ensures that alerts arrive with the context needed to support immediate action.

At the same time, expectations around automation are becoming more realistic. While machines excel at processing data and identifying patterns, analytical judgement remains essential for interpreting intent, assessing confidence, and identifying meaningful shifts in adversary behaviour. The most effective intelligence platforms combine automated processing with human-led analysis.

This balance also shapes discussions around return on investment. Customers increasingly expect intelligence tooling to demonstrate clear operational benefit, such as improved detection, faster response, or better prioritisation. Intelligence that is delivered in a form that integrates naturally into security workflows is more likely to achieve this impact.

For CTI teams and providers alike, a key consideration is deciding what should be automated and what should remain analyst-driven. Repeatable processes and large-scale data handling benefit from automation, while assessments of intent, relevance, and strategic significance continue to rely on human expertise.

In 2026, the enduring value of experienced analysts is not diminished by automation but amplified by it. By pairing scalable delivery mechanisms with consistent analytical oversight, CTI providers can deliver intelligence that is both timely and trusted. This combination is central to meeting rising customer expectations in an increasingly complex threat environment.

What This Means for CTI Teams in 2026

Taken together, these trends point to a clear evolution in how cyber threat intelligence teams must operate in 2026. The challenge is not a lack of data or tooling, but ensuring that intelligence capability is aligned with real organisational needs and outcomes. Teams that adapt their focus and ways of working will be best placed to deliver sustained value.

First, there is a renewed need to invest in analytical skills alongside technology. Tooling and automated alerting provide essential scale and coverage, but they do not replace the ability to assess relevance, weigh confidence, and draw meaningful conclusions. Developing analysts who can interpret complex activity, recognise patterns over time, and communicate insight clearly remains one of the most effective ways to improve intelligence outcomes.

Second, collection should be increasingly guided by clearly defined priority intelligence requirements. Rather than attempting to monitor everything equally, effective CTI teams focus on the threats, actors, and techniques most relevant to their organisation or customers. Well-defined PIRs help shape what data is collected, how it is analysed, and how it is delivered, ensuring that intelligence production remains purposeful rather than reactive.

Strong relationships across the security and business landscape are also essential. CTI does not operate in isolation, and its value is maximised when it is closely connected to security operations, incident response, identity and access management, and senior leadership. Regular engagement with these stakeholders helps ensure that intelligence outputs align with detection needs, response priorities, and strategic concerns.

Finally, success in 2026 is increasingly measured by influence rather than output. The most effective CTI teams are those that can demonstrate how intelligence has informed decisions, shaped defensive priorities, or enabled faster and more confident responses. Reports and alerts remain important delivery mechanisms, but their true value lies in the decisions they support.

For CTI teams navigating an increasingly complex threat environment, these principles provide a practical foundation. By combining strong analytical capability, focused collection, collaborative working, and outcome-driven measurement, intelligence teams can remain relevant and impactful in the year ahead.

Conclusion: The Evolution of CTI

Cyber threat intelligence in 2026 is evolving rapidly. What was once largely a support function is increasingly a strategic enabler, providing insight that shapes decisions across security operations and organisational leadership. Threats are faster, more complex, and noisier than ever, driven by automation, AI, and shifting geopolitical pressures.

In this environment, the differentiators for effective intelligence are context, clarity, and credibility. Understanding not just what is happening, but why it matters and how it affects the organisation, is what turns data into actionable insight. Teams that can provide this perspective, supported by robust analytical capability and integrated tooling, will be best placed to help organisations anticipate, prioritise, and respond to evolving threats.

2026 will not be defined by new types of threats alone, but by the ability of intelligence teams to interpret them, communicate their significance, and drive meaningful action. In this way, cyber threat intelligence will continue to move from reactive observation to proactive influence, ensuring its central role in organisational resilience and security strategy.

"Behind
Investigation, Opinion

Behind the Mask: Creating and Maintaining Sock Puppet Accounts for Online Research

When conducting online research or gathering open-source intelligence (OSINT), it is often necessary to observe or interact with digital spaces without revealing your true identity. This is where sock puppet accounts come into play. A sock puppet is a fictitious online identity created to access information, join closed groups, monitor activity, or engage with targets while protecting the researcher’s real identity and intent.

Used properly, sock puppets are an essential part of an investigator’s toolkit. However, their creation and use come with both ethical and legal responsibilities. Misuse can lead to legal consequences, reputational damage, or compromised investigations. Practitioners must always follow legal guidance and act within clearly defined ethical boundaries.

In this blog, we will explore how to plan, create, and maintain effective sock puppet accounts for OSINT purposes. We will discuss key operational security (OPSEC) measures, common pitfalls to avoid, and strategies for maintaining a convincing online persona over time. Whether you are new to this practice or looking to refine your approach, this guide will help you lay a solid foundation for safe and responsible online research.

What Is a Sock Puppet Account?

A sock puppet account is a false or alternate online identity used to conceal the true identity of the user behind it. In the context of online investigations and intelligence gathering, sock puppets allow researchers to access and monitor digital spaces without drawing attention to their real-world affiliations or investigative purpose.

These accounts are beneficial in OSINT investigations where anonymity is critical. They may be used to:

  • Access private or semi-restricted forums and groups
  • Observe conversations on social media without alerting subjects
  • Collect threat intelligence from Dark Web marketplaces or closed communities
  • Engage with individuals or groups in a way that does not compromise operational security

While sock puppets can be powerful tools, their use must always be underpinned by legal and ethical awareness. Investigators should never use false identities to entrap, manipulate, or harass individuals. The goal is passive information gathering, not interference or provocation. Moreover, laws governing online impersonation, data protection, and computer misuse vary between jurisdictions, and it is the investigator’s responsibility to ensure compliance.

Wherever possible, work within organisational policies, maintain internal approval processes for sensitive research, and document all actions for accountability. Ethical OSINT hinges not only on what can be done, but on what should be done.

Planning Your Sock Puppet Strategy

Before creating a sock puppet account, it is essential to define a clear objective. What do you need the account to do? Your goal might be to passively observe a forum, monitor a social media group, or engage with a specific individual or community. The purpose of the account will shape every decision that follows, from the choice of platform to the construction of your online persona.

Understanding your target environment is a crucial part of this planning stage. Different platforms have different norms, verification processes, and levels of scrutiny. A persona that appears credible on Reddit might not be believable on LinkedIn. Consider regional factors as well: language, time zone, and cultural references all contribute to the authenticity of an account. An inconsistency in these details can quickly arouse suspicion.

With your objective and environment defined, you can begin to craft a suitable cover story. This should include a basic biography, a plausible location, interests relevant to the communities you plan to interact with, and a consistent tone of voice. Keep the persona simple, but detailed enough to withstand casual scrutiny. Avoid unnecessary complexity, which can increase the risk of contradictions or mistakes.

A well-planned sock puppet starts long before the account is created. By aligning your objectives with your operational context and building a realistic backstory, you lay the groundwork for a credible and sustainable online identity.

Creating the Sock Puppet Account

Once your planning is complete, the next step is to create the sock puppet account itself. This process involves selecting the right platform, crafting a believable identity, and ensuring that your setup maintains strong operational security from the outset.

Choosing the Right Platform

Select your platform based on the objective of the investigation. If you need to observe professional activity or gather company intelligence, LinkedIn might be appropriate. For community discussions, Reddit or Discord may be more useful. For threat intelligence gathering, forums or encrypted messaging apps could be more suitable. Each platform has its own registration process, verification requirements, and user expectations, all of which must be considered.

Crafting a Believable Identity

A convincing sock puppet needs to pass casual inspection. Start with a realistic username and a dedicated email address that fits your persona. Avoid using anything that resembles your real name or any identifiers linked to your organisation.

  • Profile photo: Use AI-generated images or copyright-free alternatives. Tools like ThisPersonDoesNotExist or Generated Photos can be helpful, but check for anomalies that might raise suspicion.
  • Biography and interests: Write a brief, plausible bio that fits the persona and platform. Add relevant interests or affiliations to make the account appear active and authentic.
  • Posting behaviour: Mirror the tone, grammar, and posting frequency typical for the platform and user type. If your persona is a 30-year-old from Manchester, for example, ensure the language and topics reflect that identity.
  • Language consistency: Stick to one language and dialect throughout. Switching between different styles or regions can be a clear indicator of inauthenticity.

Acquiring a Clean IP

To prevent your real identity or location from being linked to the sock puppet, use a clean and separate IP address. A reputable VPN or proxy service is essential, and in some cases, a dedicated virtual machine or separate device should be used. Avoid logging in to real accounts or using your usual browser within the same environment, as cross-contamination can compromise the entire operation.

Account creation is not just about filling in a form. Every detail, from your profile picture to your browser setup, contributes to the believability and security of the puppet. Take your time, document each step, and treat the identity as if it were real.

OPSEC Considerations

Operational Security (OPSEC) is critical to the effective use of sock puppet accounts. Without proper precautions, it is easy to leave digital traces that link back to your real identity or organisation. To maintain credibility and protect yourself, you must build strong habits around device use, network hygiene, and identity compartmentalisation.

Device and Network Isolation

Always use a dedicated environment for sock puppet activity. This might be a virtual machine (VM), a separate user profile, or an entirely distinct physical device. The key is to ensure that no personal data, saved credentials, or browsing habits from your real identity carry over into the puppet’s digital footprint. Similarly, connect via a trusted VPN or proxy with a location appropriate to the persona. Never use your home or work IP address when managing sock puppets.

Avoiding Contamination

Cross-contamination with real accounts is one of the most common OPSEC failures. Use a clean browser instance with no saved cookies, autofill data, or extensions that may reveal identifying information. Consider using privacy-focused browsers or containerised browsing sessions to isolate activity. Disable features like browser synchronisation or automatic logins, which could leak personal credentials.

Using Burner Phones and Anonymous Email

When platforms require phone numbers for verification, use a burner device or a secure, anonymised SMS service, provided it complies with legal and policy requirements. Similarly, choose privacy-conscious email providers such as ProtonMail or Tutanota. The email address should align with the puppet’s identity and not reference any real-world details.

Password and Account Recovery Separation

Treat sock puppets as standalone entities. Use unique, complex passwords for each account and manage them using a secure password manager. Keep recovery options consistent with the identity – never link your real email or phone number. If using recovery questions, invent answers that match the puppet’s backstory and document them securely.

Logging and Documentation

Maintain secure records of your sock puppets, including account details, access credentials, personas, activity logs, and creation dates. This helps track usage over time, identify potential compromises, and safely retire or rotate identities when needed. Store this information in an encrypted format or within a secure password management tool.

Sock puppet OPSEC is not about one-time precautions – it requires ongoing discipline. A single mistake can expose your identity or compromise the entire investigation. Take a cautious, methodical approach and revisit your OPSEC practices regularly.

Maintaining Sock Puppets Over Time

Creating a sock puppet is only the beginning. To remain credible and useful over time, the account must appear active, consistent, and authentic. Dormant or obviously artificial profiles are more likely to be flagged by platforms or ignored by the communities you are trying to observe. Maintaining a sock puppet means simulating the behaviour of a genuine user, without attracting unnecessary attention.

Simulating Real Behaviour

Regular interaction is key to building a believable presence. Depending on the platform, this might include:

  • Liking or sharing posts
  • Following relevant accounts or joining groups
  • Commenting or replying in a manner consistent with the persona

These interactions should be contextually appropriate and contribute to the puppet’s credibility. For example, a user who claims to be interested in cybersecurity might follow industry influencers, comment on relevant articles, or share news stories.

Scheduling Realistic Activity Patterns

Sock puppets should reflect normal online behaviour. Consider the timezone and daily schedule of the persona. If your puppet claims to be based in Berlin, it would be unusual for them to post at 3 a.m. local time. Avoid excessive or erratic posting, which can appear automated or suspicious. A light but consistent activity pattern over time is more convincing than bursts of high engagement.

Avoiding Automation Red Flags

Some platforms are aggressive in detecting and removing accounts that behave like bots. Avoid scripted or repeated actions, especially immediately after account creation. Do not mass-follow users or copy-paste identical comments across threads. Behave like a real person – slow, deliberate, and occasionally imperfect.

Regularly Updating Profile Content

Real users update their profiles from time to time. Refresh your puppet’s bio, add a new interest, or change a profile picture occasionally to reflect life events or shifting interests. These subtle changes reinforce the illusion of an active, evolving online identity.

Ultimately, a successful sock puppet account blends in. It should quietly accumulate a digital footprint that supports its cover story and gives you access to the information you need, without ever drawing attention to itself.

Risks, Red Flags, and Account Burnout

Even well-crafted sock puppets carry risk. Platforms continue to improve their ability to detect suspicious behaviour, and users themselves may flag accounts that appear inauthentic. Understanding common warning signs and knowing when to retire or rotate an identity is key to maintaining long-term operational capability.

Common Ways Sock Puppets Get Flagged or Banned

Sock puppets may be suspended or deleted for a range of reasons, including:

  • Logging in from multiple geographic locations in a short space of time
  • Sudden spikes in activity (e.g. mass liking, following, or posting)
  • Use of stock or AI-generated profile images that resemble known fake accounts
  • Repeated use of the same contact details, browser fingerprint, or device setup
  • Lack of meaningful interaction or organic growth over time

Even a single policy violation can draw scrutiny, particularly on mainstream social media platforms where automated systems are quick to act.

Avoiding Repetitive Patterns Across Accounts

If you operate multiple sock puppets, ensure that each has a unique and independent identity. Reusing the same backstory, writing style, or image sources across accounts can make them easier to detect and link together. Separate devices, email addresses, and behavioural traits help to isolate each puppet and reduce the risk of a cascading compromise.

When to Retire a Puppet and How to Replace It Safely

No sock puppet should be considered permanent. If an account is inactive, becomes untrustworthy, or begins attracting unwanted attention, it is often safer to retire it than to try and recover its credibility. Before deletion, remove any content that could be linked to other operations. Keep a log of why it was retired, and plan how a replacement will fill the same role with improved safeguards.

Having Backup Identities Ready

To ensure continuity, it is good practice to maintain a small number of standby identities.  This is sometimes referred to as a “puppet farm”. These can be developed gradually in the background, gaining basic credibility over time, so they are ready to use when needed. In some cases, it may also be appropriate to establish layered personas, where one puppet supports or interacts with another to enhance realism.

Maintaining sock puppets is an operational task that requires regular attention. The digital landscape shifts constantly, and even the most convincing puppet may eventually outlive its usefulness. Being prepared to adapt is vital.

7. Tools and Resources

Successful sock puppet operations depend not only on planning and technique, but also on using the right tools to support anonymity, security, and realism. The following categories highlight essential resources for anyone managing online personas, with emphasis on privacy-focused solutions.

VPNs and Secure Browsers

To prevent IP address leaks or location-based flags, always connect through a reliable virtual private network (VPN). Services such as Mullvad or Proton VPN offer privacy-focused features without logging user activity. In addition, using secure or privacy-hardened browsers, such as Firefox with privacy containers, Brave, or Tor Browser, can help prevent tracking and cross-contamination between real and sock puppet identities.

For advanced operations, consider launching sock puppets within secure environments such as Tails OS or a hardened virtual machine to reduce the digital footprint even further.

Image Generation Tools

Choosing a believable profile image is vital. AI-generated photo tools like ThisPersonDoesNotExist or Generated.Photos create unique images that are not traceable to real people, reducing the risk of impersonation claims. However, these images should be reviewed carefully for visual anomalies that might suggest they are artificial. Alternatively, use licence-free photo repositories where permitted.

Secure Email Services

Every puppet should have its own email address from a secure, privacy-conscious provider. Services such as ProtonMail, Tutanota, or Mailfence are widely used for this purpose. Avoid mainstream providers that require phone verification or link accounts to existing profiles. Where possible, create the email account using the same VPN and device you plan to use for the puppet itself.

Password and Identity Managers

Managing multiple identities requires strict separation and secure record-keeping. Tools like Bitwarden, KeePassXC, or 1Password can be used to store login details, backstory notes, recovery options, and activity logs in an encrypted format. Avoid reusing passwords or security questions across accounts, and clearly label each identity to avoid mistakes.

Burner Phone and SMS Services

Some platforms require phone number verification. Where legally permitted, use burner phones or temporary SMS services to meet this requirement. Options include physical SIMs with disposable devices or online services such as MySudo or Silent Link, though reliability and legality vary by region. Never use your personal or work number under any circumstances.

A well-prepared toolkit makes managing sock puppets more secure, efficient, and scalable. Review your tools regularly, keep backups where needed, and ensure you remain up to date with changes in platform behaviour or verification processes.

Final Thoughts and Best Practices

Sock puppet accounts are powerful tools for legitimate online research. When used responsibly, they enable investigators, analysts, and researchers to access vital information, monitor digital threats, and engage with online communities without exposing their true identity. However, with this capability comes a significant ethical and operational responsibility.

These accounts should never be used to deceive, manipulate, or harm individuals. Their purpose is to observe, gather intelligence, and support investigations that serve the public interest or protect organisations from threats. Operating within legal boundaries and upholding professional standards is essential.

The digital landscape is constantly changing. Platforms evolve, detection methods improve, and user behaviour shifts. This means sock puppet strategies must also be regularly reviewed and refined. What works today may not be effective tomorrow, so ongoing learning and adaptation are key to maintaining both access and security.

Finally, any organisation or individual engaging in this kind of work should develop their own standard operating procedures (SOPs). These should include clear guidelines for planning, creation, use, and retirement of sock puppet accounts. Testing identities in controlled environments before deploying them for real investigations can also help identify weaknesses before they become liabilities.

Used with care, discipline, and a strong ethical framework, sock puppets can provide valuable insight while keeping investigators safe and discreet.

Red flag photo by Paolo Bendandi and sock puppet photo by Natalie Kinnear.

"Cyber
Investigation, Opinion

Beyond the Dark Web: Where Threat Actors Operate

The “dark web” has become something of a buzzword in recent years, often portrayed as the hidden underworld of the internet where cybercriminals operate in complete anonymity. For many, it conjures images of secret marketplaces, illicit data dumps, and hard-to-trace communications – all out of reach from the average internet user.

Because of this perception, it is a common misconception that all threat actor activity takes place exclusively on the dark web. While it certainly plays a role in enabling criminal operations, the truth is far more complex. Today’s threat actors are increasingly making use of platforms that are readily available, user-friendly, and in many cases, completely legal.

Much of their coordination, recruitment, and even data leakage now takes place in plain sight – across encrypted messaging apps, public forums, and mainstream social media platforms. Understanding where these actors truly operate is critical for any organisation looking to stay ahead of the threat landscape.

The Evolving Landscape of Threat Actor Platforms

The way threat actors communicate and coordinate has shifted significantly in recent years. Once heavily reliant on hidden services accessed through the Tor network, many cybercriminals are now embracing more accessible, mainstream platforms to conduct their activities.

This change has been driven by several key factors. One of the most prominent is the increased pressure from law enforcement. High-profile takedowns of dark web marketplaces such as AlphaBay and Hydra have disrupted long-standing criminal ecosystems, forcing actors to reconsider where and how they operate.

At the same time, modern platforms offer features that make them attractive to malicious users. Encrypted messaging apps provide a level of privacy that rivals, and in some cases exceeds, what is available on the dark web. Public forums and chat platforms are easy to access, require minimal technical knowledge, and can reach large audiences quickly.

For cybercriminals, scale and convenience matter. Hosting content on widely used services allows them to cast a broader net, whether they’re distributing stolen data, selling malware, or recruiting new affiliates. The lines between the open internet and covert criminal spaces are increasingly blurred, making it more difficult for defenders to track activity using traditional dark web monitoring alone.

Alternative Threat Actor Channels

While the dark web still plays a role in cybercriminal operations, many threat actors now prefer more accessible and user-friendly platforms. These alternatives offer speed, scalability, and often a surprising degree of anonymity – all without the need for specialised browsers or infrastructure. Below are some of the most commonly used non-dark web channels.

Telegram

Telegram has become a go-to platform for cybercriminals. With its end-to-end encryption, support for large group chats, and the ability to create private or public channels, it offers the ideal environment for discreet coordination at scale.

Threat actors use Telegram to:

  • Leak stolen data and documents
  • Advertise and sell credentials or access to compromised systems
  • Host scam pages or phishing kits
  • Organise affiliate networks or ransomware-as-a-service (RaaS) operations

Its minimal moderation and vast global user base make it a particularly attractive choice for cybercrime groups.

Discord and Other Chat Platforms

Originally designed for online gaming communities, Discord has evolved into a full-featured communication tool with support for text, voice, and private servers. Unfortunately, these same features have also made it a popular haven for fraudsters and cybercriminals.

Threat actors use Discord to:

  • Create closed communities centred around fraud, hacking tools, or data leaks
  • Share resources in “plug” communities – often focused on carding, identity theft, or botnet services
  • Coordinate attacks or distribute malware through seemingly innocuous links

Other platforms such as Tox, Matrix, and IRC-based services are also used, albeit with smaller user bases.

Surface Web Forums

Despite the risks of being in plain sight, many cybercrime forums continue to operate openly on the surface web. These forums are often language-specific or focused on particular sectors, such as financial fraud, social engineering, or credential stuffing.

They are typically used to:

  • Trade tools, tactics, and stolen data
  • Post tutorials or share exploit code
  • Vet and recruit participants for more private activities

Some forums operate with limited moderation or are hosted in jurisdictions with lax enforcement, allowing them to persist despite ongoing attention from security professionals.

Social Media (Twitter/X, Facebook, etc.)

Social media platforms remain surprisingly popular for certain types of threat actor activity. On services like Twitter/X, Facebook, and even LinkedIn, cybercriminals can quickly build audiences, push propaganda, or leak stolen information to make a statement.

Common uses include:

  • Publicly claiming responsibility for attacks or breaches
  • Promoting data leaks to gain notoriety or apply pressure to victims
  • Running influence campaigns or disinformation efforts
  • Recruiting low-level actors or collaborators

While these platforms generally respond quickly to takedown requests, the speed at which content can be published and spread makes them a persistent threat vector.

Paste Sites and Temporary File Hosts

Pastebin-style sites and ephemeral file hosting services continue to be used by cybercriminals to share content without needing to manage infrastructure. These services are often exploited to distribute:

  • Malware payloads
  • Indicators of compromise (IOCs)
  • Stolen credentials or internal documentation

Examples include Pastebin, Ghostbin, file.io, and anonfiles (when active). Their simplicity and temporary nature make them appealing for one-off drops or fast-moving campaigns.

Why the Shift Away from the Dark Web?

While the dark web once provided the primary infrastructure for cybercriminal marketplaces and forums, it has become a less attractive option for many threat actors. A combination of practical challenges and strategic advantages has led to a growing preference for mainstream and surface-level platforms.

One of the key drivers behind this shift is the increasing success of global law enforcement operations. High-profile takedowns such as AlphaBay, Hansa, and Hydra have not only dismantled major criminal marketplaces but also sown distrust within dark web communities. With undercover operations and seizures now a recurring threat, many actors perceive mainstream platforms as less risky in terms of operational security, particularly when combined with disposable accounts and encrypted messaging.

Technical reliability is another issue. Dark web services can suffer from poor uptime, slow performance, and hosting instability. These problems make it harder for threat actors to run consistent operations or maintain communication, especially when compared to the seamless experience offered by platforms like Telegram or Discord.

Accessibility also plays a major role. Mainstream platforms are far easier to use and require no special configuration or tools. Anyone with a smartphone can join a Telegram group or browse a fraud forum hosted on the surface web. This lowers the barrier to entry for newer or less technically skilled actors, fuelling growth in cybercriminal communities.

Finally, these platforms offer scale. Social media, public channels, and open forums provide instant access to large audiences, whether for pushing stolen data, coordinating campaigns, or recruiting collaborators. The potential for amplification far exceeds what is typically possible within the confines of the dark web.

For all these reasons, the dark web is no longer the sole or even primary location for cybercriminal activity. Threat actors are adapting to a broader, more dynamic digital environment, and defenders must do the same.

Implications for Threat Intelligence Teams

As threat actors diversify their platforms, the scope of effective cyber threat intelligence (CTI) must evolve accordingly. Relying solely on dark web monitoring is no longer sufficient. Instead, teams must broaden their visibility to include the various surface and semi-private spaces where cybercriminal activity increasingly takes place.

Monitoring closed channels such as Telegram groups, Discord servers, and niche forums has become essential. However, these spaces are often harder to access and require greater care in terms of operational security (OPSEC). Joining or observing these groups can carry significant risk if not done properly. Analysts must use hardened environments, anonymous accounts, and clear protocols to avoid detection or legal exposure.

Language skills and cultural awareness are also becoming increasingly important. Many cybercrime communities operate in non-English languages and use regional slang or coded terminology. Without this context, valuable intelligence can be missed or misinterpreted. Investing in native language analysts or translation tools can dramatically improve coverage and insight.

The scale and speed at which content is published across platforms make manual monitoring impractical. As such, automation is vital. Tools that scrape and index Telegram posts, track mentions on social media, or flag emerging IOCs can help intelligence teams respond quickly and reduce the chance of missing key developments.

Ultimately, the shift in threat actor behaviour demands a shift in defender strategy. The more fragmented and accessible the threat landscape becomes, the more agile and well-equipped CTI teams need to be in order to stay ahead.

Case Examples

LockBit’s Use of Telegram for PR and Leak Amplification (2024)

In early 2024, after suffering internal leaks and DDoS attacks against their dark web leak site, the LockBit ransomware group turned to Telegram to regain control of their narrative. The group created public Telegram channels to share statements, leak victim data, and coordinate with affiliates. This move not only ensured continuity during technical outages but also expanded their audience beyond the dark web’s limited reach.

Telegram’s encryption, ease of access, and built-in forwarding features allowed LockBit to amplify their message rapidly, including to journalists, researchers, and rival threat actors. It showcased a tactical shift: using mainstream tools as a parallel infrastructure for both influence and extortion pressure.

“Infinity Stealer” Malware Sold via Discord and GitHub (Mid–2023 Onwards)

Infinity Stealer, a malware strain targeting browser credentials and crypto wallets, began circulating heavily in 2023 via non-dark web platforms, notably Discord and GitHub. The malware was marketed in private Discord servers where prospective buyers were vetted and provided updates. GitHub repositories were used to host payloads, configuration templates, and instructions, often disguised as open-source tools.

This campaign highlights how cybercriminals are bypassing traditional marketplaces entirely, instead using legitimate platforms for both sales and delivery infrastructure. Discord’s private server structure and GitHub’s reputational cover enabled the operators to fly under the radar while still reaching a large pool of technically capable users.

Conclusion

The dark web remains a valuable source of cyber threat intelligence – but it is no longer the whole story. As cybercriminals adapt to a shifting digital landscape, they are increasingly leveraging open and semi-closed platforms like Telegram, Discord, and even mainstream social media to conduct and promote their activities.

For CTI teams, this evolution demands a broader approach. Effective monitoring now extends beyond Tor and onion domains to include a mix of channels, each with its own risks, nuances, and intelligence value. It also requires enhanced OPSEC, linguistic awareness, and the integration of automation tools to track activity at scale.

By recognising these trends and adapting monitoring strategies accordingly, defenders can stay better aligned with the current threat environment – one that is faster, more fragmented, and no longer confined to the shadows.

"Analysis
Investigation, Opinion

Mastering the Analysis of Competing Hypotheses (ACH): A Practical Framework for Clear Thinking

In an age of information overload, uncertainty, and complex decision-making, clear analytical thinking is more crucial than ever. The Analysis of Competing Hypotheses (ACH) is a structured method designed to cut through ambiguity and support objective, evidence-based conclusions. Originally developed by Richards J. Heuer, Jr., a veteran of the U.S. intelligence community, ACH was created to help analysts systematically evaluate multiple hypotheses without falling prey to cognitive biases and premature conclusions.

At its core, ACH shifts the analytical focus from proving a favoured hypothesis to disproving less likely alternatives, ensuring that conclusions are reached through a process of elimination rather than assumption. This approach is especially valuable in fields where decisions must be made in the face of incomplete or conflicting data, such as intelligence, cybersecurity, business strategy, and investigative research.

In this article, we’ll explore the foundational principles of ACH, guide you through its step-by-step methodology, and illustrate how to apply it in real-world scenarios. Whether you’re an analyst, decision-maker, or simply someone seeking to sharpen your critical thinking skills, this practical framework offers a powerful tool for navigating complexity with clarity and rigour.

What is the Analysis of Competing Hypotheses?

The Analysis of Competing Hypotheses (ACH) is a structured analytical technique that helps individuals and teams evaluate multiple possible explanations for an event, trend, or problem – all at the same time. Rather than focusing on finding evidence that supports a single favoured hypothesis, ACH encourages analysts to test all plausible alternatives and to prioritise disconfirming evidence over confirming data.

This method stands in contrast to traditional analysis, where there is often a tendency to latch onto the most obvious explanation early on and seek only evidence that backs it up. That approach, while intuitive, is prone to cognitive pitfalls such as confirmation bias, groupthink, and premature closure.

By explicitly laying out competing hypotheses and methodically evaluating each against the available evidence, ACH helps to minimise bias, highlight critical assumptions, and improve judgement, particularly in situations that are ambiguous, fast-moving, or laden with incomplete information.

Ultimately, ACH is less about finding the answer and more about narrowing down the field of possibilities through a process that is transparent, reproducible, and intellectually disciplined.

The ACH Process Step-by-Step

The Analysis of Competing Hypotheses is more than just a checklist – it’s a disciplined approach to structuring your thinking, challenging assumptions, and arriving at well-supported conclusions. Below is an expanded walkthrough of the seven core steps, each designed to promote clarity and rigour in decision-making.

1. Define the Question or Problem

A clear, unbiased problem statement is the foundation of effective analysis. This step is about narrowing the scope of inquiry and making sure the question does not contain built-in assumptions.

Tips for framing your question:

  • Avoid language that implies causality or blame
  • Be as specific as the data allows
  • Keep it neutral and open-ended

Example:
 Why did a system failure occur in a secure network?
 This framing encourages investigation without assuming intent, method, or actor.

A poorly worded question – e.g., “Who caused the attack on our network?” – limits thinking prematurely by assuming the event was malicious and externally driven.

2. List All Plausible Hypotheses

The goal here is to generate a comprehensive list of explanations for the issue. It’s critical to suspend judgment and avoid discarding possibilities too early, especially those that feel uncomfortable or less likely at first glance.

Use techniques like brainstorming, consultation with diverse stakeholders, and red teaming to uncover blind spots.

Example Hypotheses:

  • H1: Insider sabotage
  • H2: External cyberattack
  • H3: Configuration error
  • H4: Third-party service failure
  • H5: Power or environmental disruption

Even if some hypotheses seem implausible, including them ensures a more robust analysis, and sometimes the least obvious explanation turns out to be the correct one.

3. Identify Evidence and Arguments

At this stage, you gather all the information that could potentially support or contradict your hypotheses. This includes:

  • Observational data (logs, reports, witness accounts)
  • Technical indicators (malware signatures, access logs)
  • Expert assessments
  • Circumstantial clues

For each piece of evidence, evaluate two things:

  • Source reliability: How trustworthy is the origin (e.g., system logs vs. anonymous tips)?
  • Information credibility: How plausible or accurate is the content?

Also consider whether the evidence is:

  • Direct or indirect
  • Confirmed or unverified
  • Timely or outdated

Pro tip: Avoid cherry-picking. Include evidence that contradicts your initial instincts – this is where real insight often lies.

4. Analyse Consistency

This is the heart of the ACH method: building a matrix that compares each hypothesis against each piece of evidence.

You’ll mark whether each piece of evidence is:

  • Consistent with the hypothesis
  • Inconsistent (i.e., contradicts it)
  • Neutral (i.e., not relevant to that hypothesis)

Example Matrix:

EvidenceH1: Insider sabotageH2: External cyberattackH3: Configuration error
Admin account accessed remotely at 2am✔️ Consistent✔️ Consistent❌ Inconsistent
No malware signatures detected✔️ Consistent❌ Inconsistent➖ Neutral
Recent patch deployed without testing❌ Inconsistent➖ Neutral✔️ Consistent
No third-party access in logs✔️ Consistent❌ Inconsistent✔️ Consistent

This matrix helps you visualise the weight and distribution of evidence, especially in identifying which hypotheses have significant inconsistencies.

5. Refine the Matrix

Now that the matrix is populated, focus on evaluating the diagnostic value of each piece of evidence. Ask yourself:

  • Which pieces most clearly discriminate between hypotheses?
  • Are there patterns that suggest certain hypotheses are clearly weaker?

ACH places particular emphasis on inconsistencies rather than confirmations. A single strong inconsistency can eliminate a hypothesis, while consistent evidence might apply to multiple hypotheses and be less useful in narrowing options.

Refining may also involve revisiting earlier assumptions, adjusting hypotheses, or seeking new evidence to fill gaps.

6. Draw Tentative Conclusions

This is the interpretive phase – based on the refined matrix, identify which hypothesis is least burdened by inconsistent evidence. Remember, this doesn’t mean it has the most supporting evidence, but rather that it stands up better under scrutiny.

Be cautious not to overstate certainty. If multiple hypotheses remain viable, say so. ACH supports probabilistic thinking, not premature conclusions.

Key reminders:

  • Avoid selecting the “most comfortable” hypothesis
  • Document your reasoning and uncertainties
  • Stay open to revision as new evidence emerges

7. Identify Milestones or Indicators

ACH is not static. Situations evolve, and so should your analysis. Define a set of indicators – specific events, behaviours, or pieces of data – that, if observed, would confirm, challenge, or refine your conclusion.

Examples:

  • Discovery of malware indicating a known threat actor (would support H2)
  • Forensic evidence of misconfiguration traced to recent update (would support H3)
  • Repetition of similar failures in unrelated systems (might suggest a broader issue)

Establish a plan for ongoing monitoring. This step ensures your conclusions remain grounded in reality as the situation unfolds and prevents analytical drift over time.


Analysis of Competing Hypotheses

Practical Example: ACH in Action

To demonstrate the practical value of the Analysis of Competing Hypotheses, let’s walk through a realistic scenario involving a suspected cybersecurity incident at a mid-sized financial services firm. This example illustrates each step of the ACH process in context, showing how structured analysis can lead to clearer conclusions – even in the face of ambiguity.

Scenario: Unexpected System Downtime in a Secure Network

Background:
At 03:15 on a Tuesday morning, the firm’s primary transaction server went offline, causing a six-hour disruption to client services. The network is normally robust and protected by multiple layers of defence. Internal monitoring systems flagged the event, but initial diagnostics were inconclusive.

The CTO initiates an ACH analysis to determine what caused the failure.

Step 1: Define the Question or Problem

The team agrees to frame the central question as:

What is the most plausible explanation for the unexpected system outage on the secure transaction server?

This wording avoids assumptions about cause or intent and invites multiple lines of inquiry.

Step 2: List All Plausible Hypotheses

The team brainstorms and agrees on the following hypotheses:

  • H1: External cyberattack (e.g., malware, DDoS)
  • H2: Insider sabotage (malicious insider or misuse)
  • H3: Configuration or patching error
  • H4: Hardware failure or infrastructure fault
  • H5: Scheduled maintenance error or oversight

The list is deliberately inclusive to prevent tunnel vision.

Step 3: Identify Evidence and Arguments

The team compiles evidence from logs, interviews, monitoring tools, and server diagnostics. Notable pieces of evidence include:

  • E1: Server logs show a reboot command issued remotely at 03:14
  • E2: No malware signatures or IOCs (Indicators of Compromise) detected
  • E3: A new patch was installed the day prior without full regression testing
  • E4: No external traffic spikes or anomalies around the time of the incident
  • E5: Access logs show a junior administrator logged in remotely at 03:12
  • E6: Server hardware passed all post-incident diagnostics
  • E7: Change management calendar incorrectly listed maintenance for the wrong server

Each item is tagged with a confidence rating and source reliability to support judgment later.

Step 4: Analyse Consistency

The team creates a matrix to compare each hypothesis against the evidence.

EvidenceH1: CyberattackH2: Insider SabotageH3: Config ErrorH4: Hardware FaultH5: Maintenance Error
E1: Remote reboot at 03:14✔️ Consistent✔️ Consistent✔️ Consistent➖ Neutral✔️ Consistent
E2: No malware or IOCs found❌ Inconsistent✔️ Consistent➖ Neutral➖ Neutral➖ Neutral
E3: Patch installed the day before➖ Neutral➖ Neutral✔️ Consistent➖ Neutral➖ Neutral
E4: No external anomalies❌ Inconsistent➖ Neutral➖ Neutral➖ Neutral➖ Neutral
E5: Junior admin logged in remotely➖ Neutral✔️ Consistent✔️ Consistent➖ Neutral❌ Inconsistent
E6: Hardware passed diagnostics➖ Neutral➖ Neutral➖ Neutral❌ Inconsistent➖ Neutral
E7: Calendar showed the wrong server➖ Neutral➖ Neutral➖ Neutral➖ Neutral✔️ Consistent

Step 5: Refine the Matrix

Focusing on disproving hypotheses, the team notes:

  • H1 (Cyberattack) has two clear inconsistencies (E2 and E4)
  • H4 (Hardware fault) is contradicted by E6
  • H5 (Maintenance error) is weakened by E5, as the admin wasn’t scheduled to access that system

H2 (Insider sabotage) and H3 (Configuration error) remain more viable. The presence of an unscheduled login and recent patching suggests a blend of human and technical causes.

The most diagnostic evidence appears to be E2 (no malware) and E3 (untested patch), which significantly affect H1 and H3, respectively.

Step 6: Draw Tentative Conclusions

H1 (Cyberattack) and H4 (Hardware fault) are largely ruled out.
H5 (Maintenance error) is possible but lacks strong support and includes an inconsistency.
That leaves:

  • H2 (Insider sabotage): Plausible, especially with unexpected admin access
  • H3 (Configuration error): Strongly supported by evidence, with few inconsistencies

Given that the administrator may have unknowingly pushed a faulty patch, H3 is deemed the most probable hypothesis, with H2 remaining a secondary consideration requiring HR review.

Step 7: Identify Milestones or Indicators

To confirm or disprove the working conclusion, the team outlines the following future indicators:

  • Confirmation of the patch’s fault during follow-up testing (would support H3)
  • HR interview with the admin reveals intent or confusion (could support or refute H2)
  • Any signs of privilege misuse or unusual access patterns (would raise concern for H2)
  • Vendor advisory on the patch’s known issues (further supporting H3)

The analysis will be updated once these indicators are assessed. In the meantime, patching procedures are temporarily suspended, and access controls are reviewed.


Final Conclusion

The structured application of ACH helped the team reach a reasoned, defensible conclusion while keeping alternate hypotheses in play. Rather than jumping to the common assumption of a cyberattack, the analysis revealed a more mundane but equally critical root cause: likely misconfiguration following a poorly tested software update.

Real-World Reference: The Lucy Letby Case

The power of ACH is underscored by its implicit use in high-stakes investigations such as the Lucy Letby trial. Prosecutors highlighted that Letby was the only staff member present during every critical incident involving infant patients – a fact established through careful analysis of shift patterns and timelines. By systematically evaluating competing hypotheses about who could have caused harm, investigators effectively used the same logic underpinning ACH: disproving alternative explanations and focusing on the hypothesis best supported by consistent evidence. This approach helped build a compelling, structured case based on opportunity and timing, demonstrating ACH’s practical application beyond intelligence into criminal justice.

Benefits and Limitations of ACH

The Analysis of Competing Hypotheses (ACH) offers a powerful framework for navigating complex, ambiguous, or high-stakes problems. But like any method, it comes with both strengths and limitations. Understanding these helps practitioners apply it effectively and appropriately.

Benefits of ACH

1. Reduces Cognitive Bias
ACH is specifically designed to counteract common mental pitfalls, such as confirmation bias and premature conclusions. By forcing the analyst to evaluate all plausible hypotheses and focus on disconfirming evidence, it encourages objectivity and balance.

2. Encourages Structured Thinking
Rather than relying on intuition or fragmented information, ACH imposes a disciplined approach. Analysts must document each step, weigh evidence methodically, and justify conclusions. This structure makes reasoning transparent and defensible, especially important in intelligence, law enforcement, or regulatory settings.

3. Handles Ambiguity and Complexity Well
ACH is particularly effective when information is incomplete, uncertain, or contradictory. By assessing how each piece of evidence aligns (or doesn’t) with multiple hypotheses, it accommodates complexity without oversimplifying.

4. Improves Group Collaboration and Debate
In team settings, ACH helps avoid groupthink by providing a common analytical language and framework. It gives structure to collaborative analysis, enabling different perspectives to be tested against the same evidence matrix.

5. Highlights Gaps and Guides Collection
The process often reveals where evidence is weak or missing, helping analysts identify what further data needs to be gathered. Diagnostic indicators can also be flagged for future monitoring.


Limitations of ACH

1. Time-Consuming
ACH is not always suited to fast-moving or reactive situations. Building and refining matrices, especially for complex cases with numerous hypotheses, can be labour-intensive.

2. Dependent on Quality of Input
The effectiveness of ACH depends entirely on the quality and reliability of the evidence fed into it. Incomplete, misleading, or low-confidence data can skew conclusions, even if the process itself is rigorous.

3. May Oversimplify Nuance
Although ACH structures thinking, it can sometimes encourage a binary view of evidence (e.g. consistent/inconsistent/neutral). This may not capture subtleties, degrees of relevance, or contextual complexity unless analysts make an effort to interpret carefully.

4. Requires Analytical Discipline
The method assumes a willingness to challenge assumptions, avoid premature closure, and remain open to changing conclusions as new evidence arises. In practice, this intellectual discipline can be hard to maintain, especially under pressure.

5. Not a Substitute for Domain Expertise
ACH supports analysis, but it does not replace subject matter knowledge. Without expert insight to interpret evidence correctly, even a well-constructed ACH matrix can produce flawed conclusions.


ACH is a powerful complement to critical thinking, not a magic solution. Used thoughtfully, it strengthens the quality of judgment and provides a clear audit trail for how conclusions were reached.

Tools and Resources

While the Analysis of Competing Hypotheses (ACH) can be applied using simple pen-and-paper methods, various tools can help structure the process, especially when working with complex datasets or collaborating with others. Below are some practical tools that support ACH-style analysis.

Manual Tools

Spreadsheets (e.g., Excel, Google Sheets)
Spreadsheets remain a reliable and widely used method for building ACH matrices. Users can list hypotheses across the top, evidence down the side, and use consistent symbols or colour codes to mark whether each item of evidence is consistent, inconsistent, or neutral. This method offers full transparency and is easily adaptable for individual or team use.

Printable ACH Templates
Basic ACH grids are available as printable templates and can be useful in workshops, briefings, or offline environments. These encourage clarity of thought without requiring technical platforms.

Digital Tools

PARC ACH Tool
Developed by the Palo Alto Research Center, this free, downloadable tool guides users through the ACH process, including hypothesis generation, evidence scoring, matrix creation, and conclusion development. It’s well-suited for training and operational use.

IBM i2 Analyst’s Notebook
Though not purpose-built for ACH, Analyst’s Notebook allows for sophisticated mapping of relationships between people, events, and data, which can support structured hypothesis testing in investigative contexts.


Recommended Reading

  • Psychology of Intelligence Analysis – Richards J. Heuer Jr.
    The original source text on ACH offers both theory and practical examples. Essential reading for analysts across sectors.
  • Tradecraft Primer: Structured Analytic Techniques for Intelligence Analysis – CIA (declassified)
    A practical manual outlining ACH alongside other structured methods such as key assumptions checks and red teaming. Freely available online.

Conclusion

In a world increasingly defined by uncertainty, complexity, and competing narratives, the Analysis of Competing Hypotheses (ACH) offers a methodical way to cut through ambiguity. Originally developed for intelligence professionals, its value extends far beyond, offering anyone engaged in investigative work, cybersecurity, risk assessment, or strategic decision-making a practical framework for clearer thinking.

By focusing on disproving rather than confirming, ACH helps analysts avoid cognitive traps and build conclusions on firmer ground. It doesn’t guarantee certainty, but it does promote discipline, transparency, and intellectual honesty – qualities that are increasingly vital in high-stakes environments.

While the process may require time and rigour, the payoff is well-structured, defensible conclusions. Whether you’re a security analyst examining network breaches, a business leader weighing strategic options, or a researcher interpreting complex data, ACH provides a repeatable model for navigating complexity with confidence.

Incorporating ACH into your analytical toolkit is more than a method – it’s a mindset shift towards structured scepticism, clarity of thought, and resilient decision-making. The more widely it’s adopted, the stronger our collective reasoning becomes.

Header photo by Milad Fakurian on Unsplash.

Photo by fabio on Unsplash.

"SOS
SOS Intelligence Webinar

Business Update Webinar – you’re invited!

A date for your diaries, or rather, your calendar 🙂 Please join us on Wednesday, June 4th at 4pm UK time for our third webinar of the year where I will be taking you through our platform updates, and there are many!

Look forward to seeing you and taking your questions.

Best wishes,

Amir


Who is this for?

  • Anyone in a business or organisation who has responsibility for online security
  • CTOs or senior managers who want to understand why there is a critical need for a service like SOS Intelligence
  • IT / Cyber Security teams
  • Business owners who are worried about the recent cyber attacks in the UK

What we will cover:

NEW Key Features

  • SSO
  • Better UX
  • Threat Tracker
  • Domain Monitor
  • DARKMAP rebuild and improvements
  • On demand RFIs
  • Vulnerability Intelligence

Our AI Analyst

  • Fully Integrated, private LLM agent
  • Alert Analysis
  • Content Analysis
  • Natural Language querying

Hosted by Jon Moss and SOS Intelligence Founder and CEO, Amir Hadzipasic

Sign up to the webinar to receive a recording via email if you cannot attend on the day. By signing up you will also receive our newsletter for future events. You can always unsubscribe with one click.

Photo by Headway on Unsplash

"evaluating
Opinion, OSINT, Tips

Evaluating OSINT: Why It Matters and How to Do It Right

Open Source Intelligence (OSINT) has become a cornerstone of modern intelligence work – from cyber threat analysis to corporate due diligence and investigative journalism. With a wealth of publicly available information just a few clicks away, the real challenge no longer lies in accessing data, but in determining its value.

Not all sources are equal, and not all information should be trusted at face value. In an age of misinformation, spoofed identities, and manipulated content, the ability to critically evaluate OSINT is essential. Whether you’re conducting research for a security operation or building a threat profile, understanding how to assess the credibility, accuracy, and relevance of your findings is what turns raw data into actionable intelligence.

In this blog, we’ll explore why evaluation is such a crucial stage in the OSINT process, introduce key criteria and techniques for assessing intelligence, and provide practical advice to help you strengthen your evaluation skills.

Why Evaluation Matters in OSINT

The open nature of OSINT is both its greatest strength and its biggest vulnerability. While the accessibility of public data allows for rich and diverse intelligence gathering, it also means the information collected can be incomplete, misleading, outdated, or deliberately false. Without rigorous evaluation, even the most promising-looking data can lead analysts down the wrong path.

In security contexts, acting on flawed intelligence can have serious consequences – from reputational damage and wasted resources to operational failure or legal risk. A single unverified claim from an untrustworthy source can compromise an entire investigation or response effort.

It’s also important to distinguish between data, information, and intelligence. OSINT collection yields data – raw, unprocessed facts. When those facts are organised and given context, they become information. But it’s only through evaluation – the process of assessing accuracy, reliability, and relevance – that information is transformed into intelligence that decision-makers can act on with confidence.

In short, evaluation is what separates noise from insight. It’s not just a good practice – it’s a critical step that determines the overall value and credibility of your intelligence output.

Core Evaluation Criteria

Evaluating OSINT effectively requires a structured approach. Rather than relying on gut instinct or assumptions, analysts should assess each piece of information against a set of established criteria. This ensures consistency, reduces bias, and increases the likelihood that your final intelligence product will be trusted and actionable.

Here are five key criteria that can guide your evaluation process:

1. Relevance

Does the information directly relate to your intelligence requirement or objective? OSINT can be full of interesting but tangential details. Focusing only on what is relevant ensures your analysis remains targeted and efficient.

2. Reliability

Is the source trustworthy? Consider the origin of the data – is it a reputable website, a verified account, or a known organisation? Or is it an anonymous post on a forum with no verifiable backing? The credibility of the source often dictates the reliability of the information it provides.

3. Accuracy

Is the information factually correct? Has it been corroborated by other sources? Are there inconsistencies, errors, or signs of manipulation? Verifying accuracy is especially important when dealing with fast-moving events or user-generated content.

4. Timeliness

Is the data current? Outdated information can skew your analysis, particularly in areas like cybersecurity or geopolitical monitoring where things change rapidly. Always check publication dates and consider whether the information still reflects the present reality.

5. Objectivity

Is the content neutral, or does it show bias? Be wary of emotionally charged language, persuasive tone, or content designed to provoke. Identifying whether the source has an agenda can help you judge how much weight to give the information.

Using the Admiralty Code

One widely recognised method for evaluating sources and information is the Admiralty Code, also known as the NATO Source Reliability and Information Credibility grading system. It uses a two-part alphanumeric rating to assess:

  • Source Reliability (A–F) – how dependable the source is based on past performance, access to information, and known biases.
  • Information Credibility (1–6) – how believable the information is, based on corroboration, plausibility, and consistency with known facts.

For example, a rating of A1 indicates a highly reliable source providing confirmed information, while E5 might flag a questionable source offering unconfirmed or implausible content. While originally designed for military intelligence, the Admiralty Code can be adapted to OSINT workflows to provide a quick yet effective way of scoring confidence in your findings.

By combining the Admiralty Code with the core evaluation criteria above, analysts can create a more transparent, defensible assessment process that supports better decision-making.

Admiralty Code

Source Evaluation Techniques

Once you’ve identified what you’re looking for and established your evaluation criteria, the next step is to put those principles into practice. Evaluating sources effectively requires both critical thinking and a methodical approach. Below are some techniques that can help analysts assess the credibility, authenticity, and relevance of open source material.

1. Corroboration Across Multiple Sources

One of the most effective ways to validate information is through corroboration. Can the same information be found across multiple independent, reputable sources? If different, unrelated sources are reporting the same facts, confidence in the information naturally increases. Be mindful, however, of information echo chambers – where multiple outlets are simply republishing or citing the same original (and possibly flawed) source.

2. Trace the Original Source

Always seek the original source of information rather than relying on summaries, screenshots, or secondary reporting. When analysing a news story, forum post, or leaked document, trace it back to its origin to assess context, authenticity, and potential manipulation. Metadata, timestamps, and file properties can offer valuable clues in verifying source integrity.

3. Use of Source Grading Systems

Incorporating a formal source grading system, such as the Admiralty Code, adds structure to your evaluation. Assigning a reliability and credibility rating to each source not only helps prioritise information but also makes your intelligence product more transparent and defensible.

4. Evaluate Digital Footprints

For online content, take time to assess the digital presence of the source. Does a social media profile show a consistent identity over time, or does it exhibit signs of automation or inauthentic behaviour? Techniques such as reverse image searches, domain registration checks (WHOIS), and historical snapshots (via the Wayback Machine) can help verify source history and legitimacy.

5. Consider the Source’s Motivation and Bias

Understanding why a source is publishing certain information can help contextualise its reliability. Is the content investigative, promotional, political, or satirical? Is it user-generated or professionally produced? Analysing tone, language, and publication history can reveal bias or intent that may affect credibility.

Balance Automation with Human Judgement

6. Balance Automation with Human Judgement

While automated tools like browser plugins, scraping utilities, and AI classifiers can assist in sorting and filtering OSINT, human evaluation remains essential. Algorithms can flag suspicious patterns, but they may miss nuance, satire, or contextual subtleties. The most effective OSINT analysts use tools to support – not replace – critical thinking.

By applying these techniques consistently, analysts can reduce the risk of misinformation, increase the quality of their assessments, and build intelligence that decision-makers can trust. Evaluation isn’t just a stage in the process – it’s an ongoing discipline throughout the lifecycle of any OSINT investigation.

Practical Tips for Evaluators

Even with a solid framework and a set of reliable techniques, OSINT evaluation often comes down to the fine details – the subtle clues, the consistency checks, and the instinct honed by experience. This section offers practical, hands-on advice to help you refine your evaluation skills and avoid common pitfalls.

1. Keep an Evaluation Log

Maintain a record of how you’ve assessed each source – including decisions around credibility, context, and any verification steps taken. This is especially important in collaborative environments or when intelligence may need to be defended later. Tools like analyst notebooks, spreadsheets, or structured databases can help you track this clearly.

2. Use Source Checklists

Create a simple checklist to run through each time you assess a source. This could include prompts like:

  • Does the source have a known history or digital presence?
  • Is the information supported by others?
  • Can I identify any potential bias?
  • What’s the Admiralty Code rating?
     Having a repeatable checklist reduces oversight and builds consistency in your process.

3. Beware of Confirmation Bias

It’s easy to give more weight to information that aligns with your assumptions or desired outcomes. Make a conscious effort to challenge your own conclusions by seeking contradictory or alternative views. A good analyst considers what’s missing, not just what’s present.

4. Apply Lateral Reading

When evaluating websites or media content, use lateral reading – that is, open other tabs to research the author, domain, or claims from outside sources rather than staying within the original source’s ecosystem. This is especially useful when verifying unfamiliar outlets or detecting disinformation.

5. Factor in Context and Culture

Context matters. A piece of content that appears misleading may be satire, a mistranslation, or culturally specific. Understanding the context in which content was created – including language, location, and intended audience – can significantly impact how it should be interpreted and evaluated.

6. Treat OSINT Like Evidence

Approach OSINT evaluation with the same care and scrutiny as if you were handling physical evidence. Every claim should be backed by verification or flagged as unconfirmed. If there are gaps or assumptions, make them explicit. This rigour supports better intelligence products and protects your credibility as an analyst.

Tools That Support OSINT Evaluation

While critical thinking is at the heart of any good OSINT evaluation, the right tools can streamline your workflow, support verification, and uncover valuable context. These tools don’t replace human judgement – but they do enhance your ability to assess the reliability, credibility, and relevance of open source material.

Below is a selection of tools, grouped by function, that can support your evaluation efforts:

Source Verification and Reputation

  • WHOIS Lookup (e.g. Whois.domaintools.com, ViewDNS.info)
     Check domain registration details to assess how long a site has been active and who owns it.
  • Wayback Machine (archive.org)
     View historical versions of web pages to track changes or confirm the existence of content at a given time.
  • DomainTools Iris or RiskIQ PassiveTotal
     More advanced tools for investigating infrastructure, subdomains, and digital footprints of websites.

Media and Content Verification

  • Google Reverse Image Search / TinEye / Yandex
     Check whether images are original or reused across different contexts, possibly indicating misinformation.
  • InVID / WeVerify Toolkit
     Useful for verifying videos and images from social media, checking for manipulation or date/location mismatches.
  • Metadata Extractors (e.g. ExifTool)
     Analyse image and file metadata to identify origin, device, and timestamps – where available.

Social Media Evaluation

  • Account Analysis Tools (e.g. WhoisThisProfile, Social Searcher)
     Evaluate the activity and legitimacy of social media accounts by checking post history, bio details, and follower patterns.
  • Hoaxy
     Visualises how information spreads across Twitter – useful for identifying echo chambers, bots, or coordinated disinformation.

Information Cross-Referencing

  • Google Advanced Search / Operators
     Use search modifiers (like site:, intitle:, or filetype:) to hone in on credible or official sources.
  • OSINT Framework (osintframework.com)
     Not a tool itself, but a curated directory of tools and resources for various OSINT tasks – including evaluation and verification.

Structured Evaluation and Analysis

  • Maltego
     Helps visualise and map relationships between entities (people, domains, IPs, etc.), useful for contextualising source networks.
  • Hunchly
     A browser plugin that automatically captures and logs every page you visit, supporting transparency and traceability in your investigations.
  • IntelTechniques Workbook / Casefile
     Structured templates and tools from the OSINT community that support methodical evaluation and reporting.

Case Study: Misidentification in the Boston Marathon Bombing

The 2013 Boston Marathon bombing provides a powerful example of how poor OSINT evaluation can lead to serious consequences. In the immediate aftermath of the attack, online communities – particularly Reddit – attempted to crowdsource intelligence to help identify the perpetrators.

The OSINT Effort

Amateur investigators analysed photos, videos, and social media posts to spot “suspicious” individuals in the crowd. One person in particular, Sunil Tripathi, a missing university student, was misidentified as a suspect based on vague visual similarities and unverified assumptions.

Reddit threads, Twitter posts, and even some journalists picked up on the speculation, causing his name and photo to circulate rapidly online. This led to distress for his family, public confusion, and the further spread of misinformation.

What Went Wrong?

  • No Source Validation: The photos used were low-resolution and out of context. No effort was made to verify the original source or timestamp.
  • Lack of Corroboration: Claims were amplified without independent verification or official confirmation.
  • Confirmation Bias: Users were looking for someone who looked like they could be a suspect, rather than critically evaluating the data.
  • Absence of a Structured Framework: There was no use of a system like the Admiralty Code to assess source reliability or information credibility.

The Impact

Authorities later confirmed that Tripathi had no involvement in the bombing – he had sadly died by suicide prior to the attack. The incident highlighted how untrained use of OSINT and failure to properly evaluate information can lead to serious reputational harm, emotional trauma, and the derailment of actual investigations.

This case shows that while open source intelligence can be powerful, it must be used responsibly. Without evaluation, it’s just noise – and in high-stakes situations, that noise can do real damage.


Conclusion: Evaluation Is the Heart of Effective OSINT

Open source intelligence has become a cornerstone of modern investigations, from cybersecurity and law enforcement to journalism and corporate risk. But the sheer volume of available information means that gathering data is no longer the hard part – evaluating it is.

As we’ve seen, the effectiveness of OSINT hinges not on what you collect, but on how you assess it. Poorly evaluated intelligence can mislead, cause harm, or result in missed opportunities. In contrast, well-evaluated OSINT builds clarity, confidence, and strategic value.

Whether you’re using the Admiralty Code, applying structured frameworks, or leveraging specialised tools, the goal remains the same: to produce intelligence that is accurate, reliable, and actionable. Evaluation isn’t a final step in the OSINT process – it’s woven throughout.

In an age where misinformation spreads faster than truth, the ability to critically evaluate open source material isn’t just a skill – it’s a responsibility.

Header Photo by Mike Kononov on Unsplash, balance Photo by Jeremy Thomas on Unsplash and tools Photo by Immo Wegmann on Unsplash.

1 2 3 … 5 6
New: Attack Surface Management · Dark web intelligence. Now with the bigger picture. | Explore SOS Intelligence ASM →
Privacy Settings
We use cookies to enhance your experience while using our website. If you are using our Services via a browser you can restrict, block or remove cookies through your web browser settings. We also use content and scripts from third parties that may use tracking technologies. You can selectively provide your consent below to allow such third party embeds. For complete information about the cookies we use, data we collect and how we process them, please check our Privacy Policy
Youtube
Consent to display content from - Youtube
Vimeo
Consent to display content from - Vimeo
Google Maps
Consent to display content from - Google
Spotify
Consent to display content from - Spotify
Sound Cloud
Consent to display content from - Sound